345 points Jowsey 2 hours ago 182 comments

shaohua 1 hour ago | parent

"We Must Pace the Frontier"?

enjoyyourlife 1 hour ago | parent

"We must start a cartel with Google, Meta, and OpenAI"

redox99 1 hour ago | parent

This probably doesn't move the frontier, it just sits at the current frontier (opus 5.5).

Chinese models never agreed to the pacing anyway lol.

Alwayshasbeeb 1 hour ago | parent

Maybe not the raw intelligence/bench frontier but probably the cost per intelligence frontier.

redox99 1 hour ago | parent

Not for sub prices (Claude plan is way cheaper than Kimi API prices)

SomeonesAccount 1 hour ago | parent

No AA scores yet.

minimaxir 1 hour ago | parent

Page isn't up but it's a 55 (4th overall) https://x.com/ArtificialAnlys/status/2113688083145314416

Jowsey 1 hour ago | parent

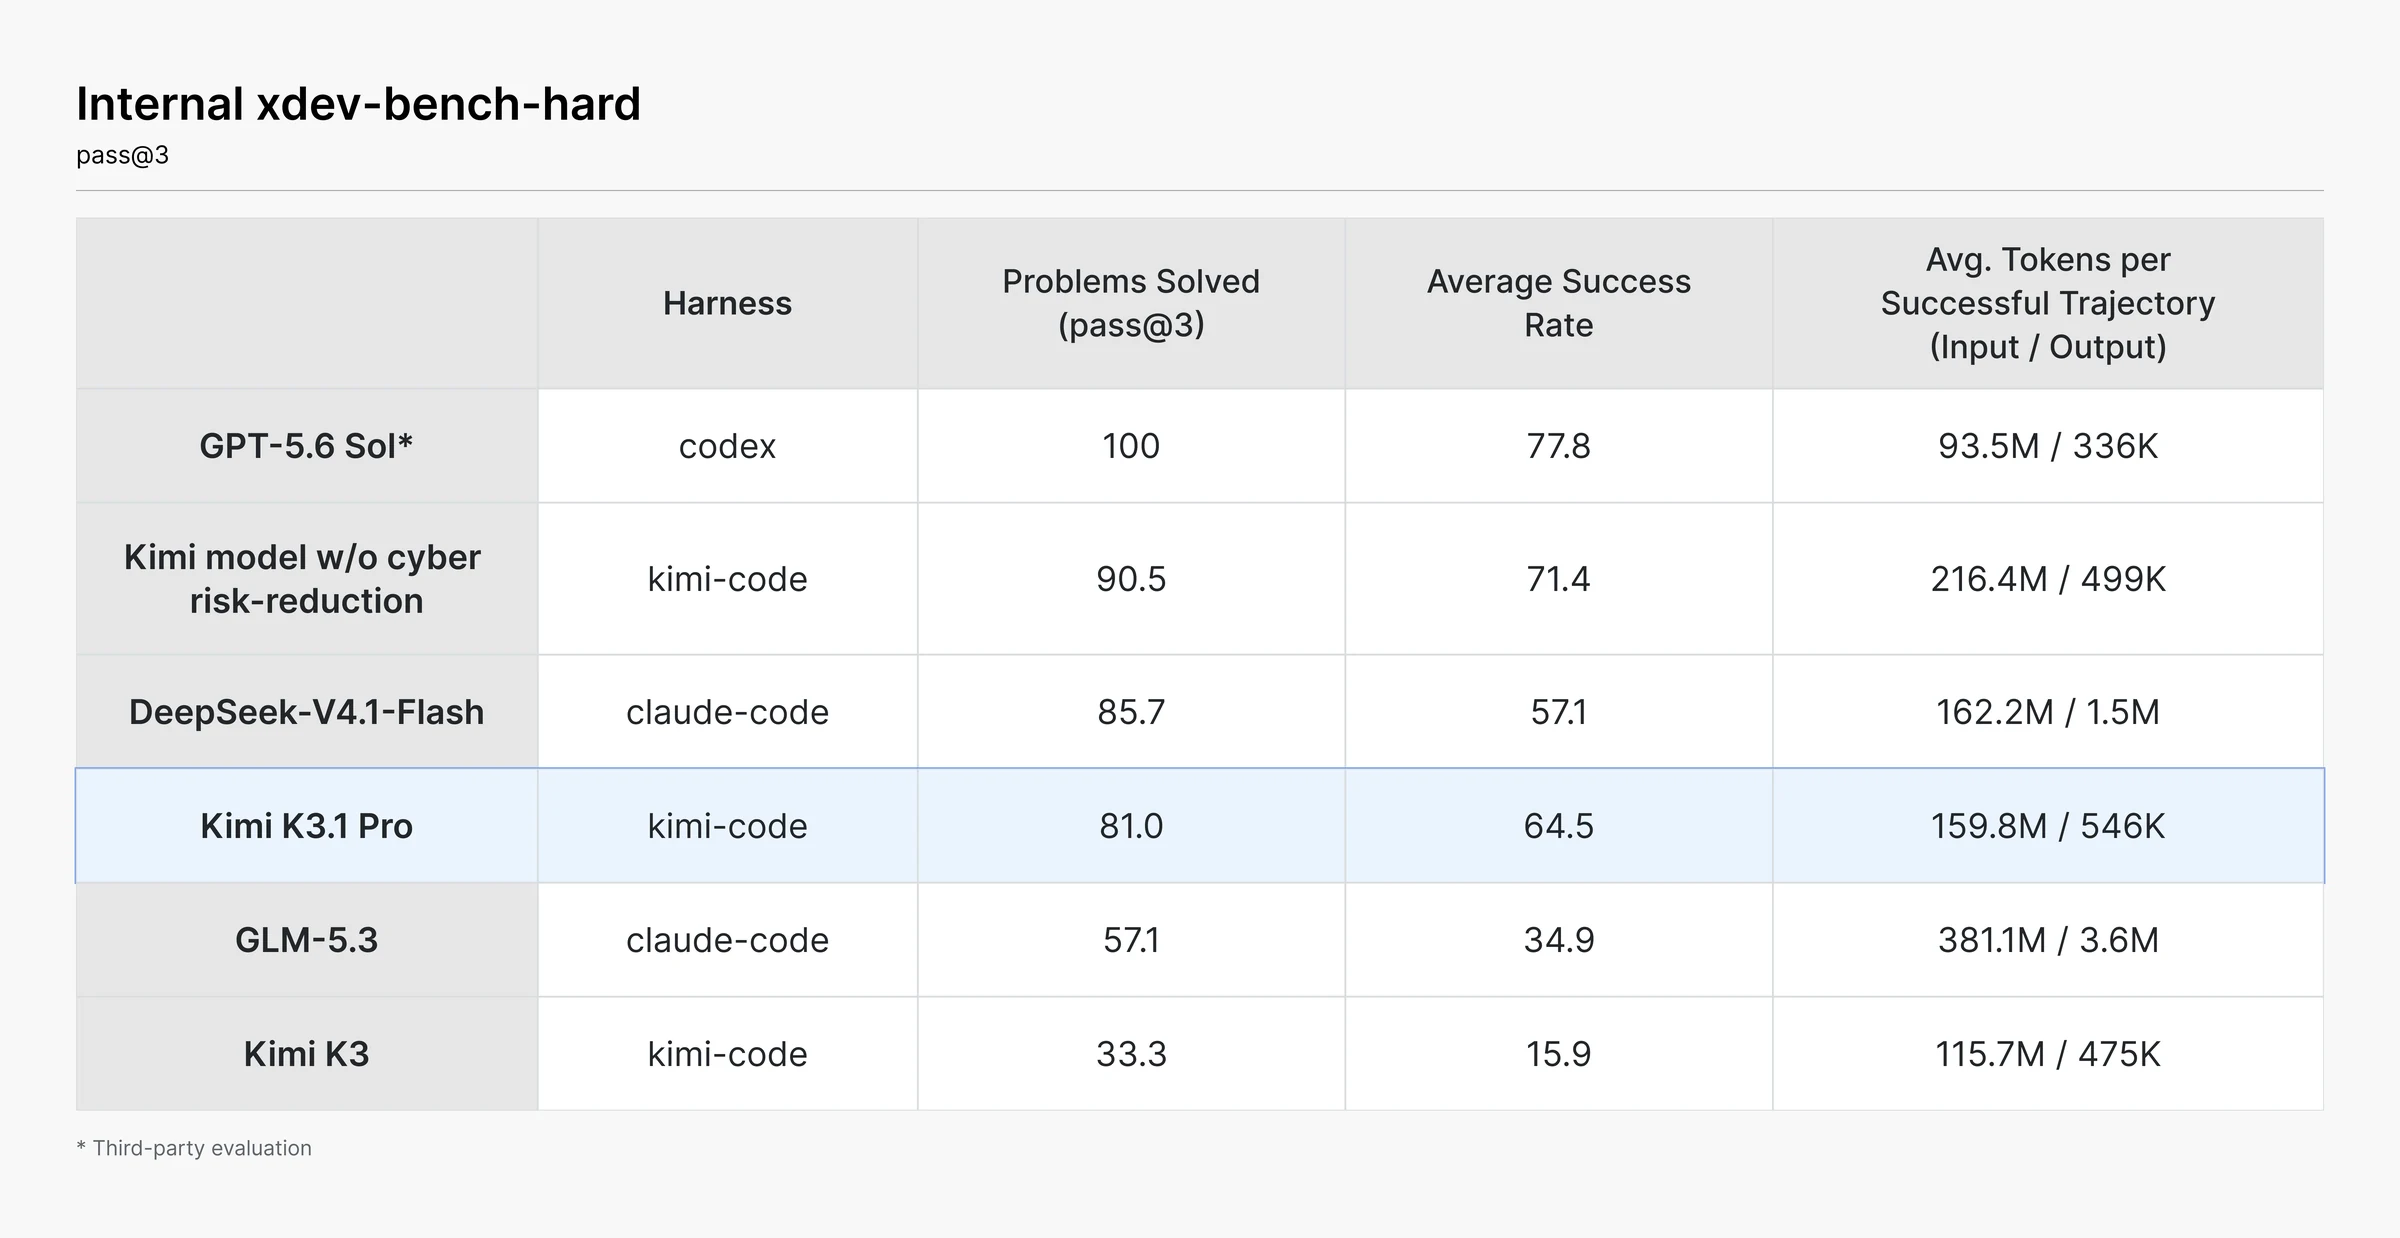
Tech blog and benchmark scores now available here: https://www.kimi.ai/blog/kimi-k3-1-pro

It appears to be generally frontier-level.

rafaelero 1 hour ago | parent

That's nuts.

volf_ 1 hour ago | parent

That's quite an impressive jump

Aboutplants 1 hour ago | parent

If those are true then wow

j_maffe 1 hour ago | parent

This is insane. Can we switch the linked page to this?

cogman10 1 hour ago | parent

I've not tried it out, but in the past I've been pretty disappointed in the performance of Kimi models. Deepseek, Qwen, and GLM all appear to perform much better even though Kimi often has higher benchmark scores. Ditto for Mimo.

cmrdporcupine 1 hour ago | parent

Yep, and often actually very expensive to use. More expensive than the frontier models because there's no realistic coding plan.

RussianCow 1 hour ago | parent

The older Kimi K models (2.5 and 2.6) weren't bad for the time, but all of their models have had problems with overthinking. This also makes them significantly more expensive in practice than their pricing suggests, since they produce way more output (reasoning) tokens than most other models. Anecdotally, I've also had problems with all the pre-K3 models thinking themselves in circles trying to solve very simple problems that other models didn't struggle with. (I haven't played with K3 much because it's just too expensive.)

akazantsev 29 minutes ago | parent

Same for me, however! Check the price-per-task table. They claim to be cheaper than GLM 5.3.

Edit: or they lie... https://artificialanalysis.ai/models/kimi-k3-1-pro

InsideOutSanta 43 minutes ago | parent

I have the opposite impression. I find K3 to be extremely capable at full-stack work; its UI design skills are great. I'd love to use it more, but the quota on Kimi's plans is abysmal. I wonder if these new models improve that.

d0mine 3 minutes ago | parent

[delayed]

WASDx 1 hour ago | parent

Their benchmark result table is broken in Firefox.

yorwba 44 minutes ago | parent

  document.querySelector("table").style["table-layout"] = "auto";

sergiotapia 1 hour ago | parent

Holy fuck

doctoboggan 49 minutes ago | parent

I always assume they are benchmaxxed until proven otherwise.

peri-cl 27 minutes ago | parent

How many frontier labs are there right now? There's 5 independent groups neck-and-neck on the benchmarks, right?

A few weeks ago it was 2. Argon happened 23 days ago; Muse Wonder was 11 days ago.

nater5000 6 minutes ago | parent

You either include all labs which can reasonably produce models which are capable enough to be considered generally on-par with the best available models, in which case there has been way more than 2 frontier labs for a while now, or you take a more literal definition and only include labs which are capable of producing models which are considered "the best" out there, in which case there are basically just 2.

I think the former definition is a bit more meaningful since it avoids issues with determining what actually constitutes "the best" model out there. In that case, Google has been a frontier lab for a long time, Meta arguably as well, and you're also ignoring xAI which has been competitive for a while now. And, obviously, there's a bunch of Chinese labs which would deserve the title as well.

But if one is being strict (and willing to accept generally accepted definitions/measures/etc.), then there has only ever been two frontier labs: OpenAI and Anthropic. They're the only labs to have had "the best" models at any point in time since LLMs became a thing.

reissbaker 5 minutes ago | parent

Moonshot has been frontier since this summer. At this point whenever they release a model it's on par with whatever the latest OpenAI/Anthropic model release was.

Not sure I'd put Google there in practice. And while Muse is an impressive jump from behind it's still not quite at the frontier either IMO.

margalabargala 5 minutes ago | parent

Muse Wonder is good but it's not frontier. It goes neck and neck with Opus 5.

metalliqaz 2 minutes ago | parent

I'm not sure what counts anymore. You've got OpenAI and Anthropic; then Meta, Google, and X; then over to Alibaba/Qwen, Z/GLM, Moonshot/Kimi, Deepseek; and Mistral in Europe. How many people out there in the real world can actually come up with tasks that differentiate those 10?

cromka 17 minutes ago | parent

Can someone please tell me what benchmarks to look for that measure world knowledge? For sspitballing, critical analysis, business projects, etc. Is the model size the only way to measure it?

rudolftheone 1 hour ago | parent

Hallu Bench Hard: K3 at 23.4%, K3.1 at 8.3% which is very nice improvement!

brianritz 1 hour ago | parent

Maybe this was why the “AI trade” was weak this week.

throwa356262 1 hour ago | parent

Ah, the version available to us mortals is nerfed in cybersecurity just like the US models :(

anderber 1 hour ago | parent

It seems that GLM-5.3 is still the go-to for cybersecurity.

TuxSH 1 hour ago | parent

> For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.

Lame.

AspireOne 49 minutes ago | parent

I like it. If the increase in unrestricted cyber capabilities can be slowed down, please be it. The world needs to get ready, and that takes time. Way more time than even a slow progress would allow.

Unless you want to see more of what happened the past few days.

I think the argument that "cyber capabilities should be democratized, thus keep producing them now, fast, and for everybody" is a very naive one.

moecables 1 hour ago | parent

Great! next week we'll get Astra 6.1 and Fable 5.2

onlyrealcuzzo 2 minutes ago | parent

Probably something like:

GLM -> Qwen -> DeepSeek (pro) -> Gemini (Carbon) -> Fable (to beat Carbon) -> Astra (to be slightly worse than Fable but cheaper).

I doubt we'll see any major US release besides Grok in the next 3 weeks.

The fun part is, we're already at the point where we are seeing something frontierish almost every single week.

wolttam 1 hour ago | parent

It's a bit fascinating to me how all of these labs have rolled their own (it sounds like) completely unique RL environments.

I wonder how much the industry will centralize around a few key patterns, and if we'll start to see some RL framework projects gain traction and be used by the bigger labs

P.S. weights by November 4th

Philpax 1 hour ago | parent

Eh, not necessarily, many of the RL vendors sell to Chinese labs, too: https://www.interconnects.ai/p/glm-53-how-chinese-labs-keep-...

rudolftheone 1 hour ago | parent

That's something which caught my attention:

> First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights.

So they admit that they could do more, but they won't?

segmondy 1 hour ago | parent

They don't want to be banned, and maybe their best offensive cyber capability models will be for their govt.

Onavo 1 hour ago | parent

The more interesting question is how much more performance can be squeezed out by post training the open weights through RL.

scottyah 1 hour ago | parent

Or it's a cop out. I could totally outrun Usain Bolt, but by design I don't push to set new World Records. I will increasingly show faster times though.

stalfie 1 hour ago | parent

Well, in the publication they claim to have identified specific cybersecurity post training tasks that nerfed capabilities when they removed them, which seems like a reasonable methodology.

Seeing as no one besides blackhats want frontier cybercrime capability to be open source, this seems like a very sensible thing to do.

So they have published a reasonable means, and they have a motive. I'd put my money on "probably true".

ApolloFortyNine 1 hour ago | parent

The problem is, as anyone trying to address security concerns in claude can attest to, the guardrails trigger even when trying to address real bugs. Good cyber defense requires an understanding of the offense.

How you avoid the "fix my code" attack, the code being someone else's code, I do not know. But nerfing the model doesn't seem like the best path forward either.

zozbot234 1 hour ago | parent

This is not about guardrails, it's just not post-training the model on tasks that specifically relate to cyber-offense. It's a very lightweight intervention, and it makes the model less of a target for bad actors.

tough 47 minutes ago | parent

claude code "auto-mode" uses a smaller sonnet-like model for classifying, which means it's basically dumb, and the harness biases it into denials

CBLT 1 hour ago | parent

Please don't change "cybersecurity" to "cybercrime" from one sentence to the next as a rhetorical flourish. It comes off as disingenuous and makes it harder to get your real point across.

zozbot234 1 hour ago | parent

"Cybersecurity" as a general term often includes offensive "cyber" which is what is being talked about here.

LtdJorge 47 minutes ago | parent

It would also be very sensible to offer a BlackHat Pro version to national officials, for them.

InsideOutSanta 46 minutes ago | parent

> Seeing as no one besides blackhats want frontier cybercrime capability to be open source

Sure. The problem is that there is no practical difference between "cybercrime capability" and "cybercrime defense capability."

All of my PRs go through an adversarial security review by GLM-5.3, because it's the only smart-enough model with a good understanding of cybersecurity issues that won't regularly refuse the job. Removing that ability from frontier models helps nobody except cyber criminals.

ben_plotke 43 minutes ago | parent

> Seeing as no one besides blackhats want frontier cybercrime capability to be open source

I'm not interested in black hat anything, but I am very invested in making sure the products I work on are not compromised. Given that state agencies have "frontier cybercrime capability", I would like to have the same.

Mattwmaster58 1 hour ago | parent

This doesn't seem particularly notable and is in line with Anthropic and OpenAI's approach of restricting release/access to more capable models.

_factor 1 hour ago | parent

It is notable in that it’s the first time an open Chinese company openly stated they were reducing intelligence for “safety”.

“Our lock can be picked by the robot.” We ban the robot instead of fixing the lock. It’s shortsighted.

JoshTriplett 1 hour ago | parent

If we had a technique that would defeat almost every lock in the world, we might be prudent to delay releasing that until people have had time to change the locks.

Same general benefit as coordinated disclosure, except it's a big game-theory problem where we're likely to eventually have sufficiently capable defectors.

vikramkr 17 minutes ago | parent

they're pretty clearly framing it as holding back on the robot and letting is lose slowly to give everyone time to update their locks

revolvingthrow 1 hour ago | parent

Yeah that's a huge downside. That the model does the task without tripping over its own feet, like discovering a vulnerability the model itself accidentally built 15 minutes ago and triggering its own guardrails, made the Chinese models attractive to use for security-adjacent things. Also useful to red-team your own stuff. While I can understand the reasoning behind it (and I guess having a model that's really good at both offense and defense released into the ether could lead to CCP asking some very pointed questions if Moonshot managed to get blamed for some incident stemming from their model's misuse) it's still a huge disappointment.

I don't want to give US labs the results of my DNA tests and my family tree going back to the 16th century just to secure my shitty app, but if the Chinese are bowing out as well it seems the only alternative is to admit that some script kiddie with a bunch of tokens will just pwn you now and then.

0xWTF 1 hour ago | parent

> I don't want to give US labs the results of my DNA tests

My friend, you realize that if you have had blood drawn for a genetic test, there is a very decent probability that the sequencing was done by a Chinese lab operating in the US, right? The Chinese probably have more US genomes that the US does.

https://pandorareport.org/the-gryphon-scientific-biosecurity...

Also, illumina used to ship products with hardcoded S3 access, so purchasers of used equipment could gain access to sequencing information generated by the original owners. Too many links to cover all of it, here's the Gemini summary:

https://share.google/aimode/4JLsHpeRCWlVqU8qT

arjie 1 hour ago | parent

If the Chinese want it, they have it. BGI does an enormous amount of sequencing. My own genome is entirely public (or was, and will be again when/if Personal Genome Project comes back) so you can watch and see if it harms me.

TrainedMonkey 1 hour ago | parent

On the surface that seems like a responsible thing to do

WarmWash 1 hour ago | parent

All it takes is one idiot who happens to have the resources to "pWm Teh Interwebs" to scare both the US and Chinese governments.

woadwarrior01 1 hour ago | parent

Kimi is the closest Chinese equivalent of Anthropic.

henry700 1 hour ago | parent

Yeah but not hypocritical

zozbot234 1 hour ago | parent

It's not actively nerfed like the Western frontier models, it's just downweighting offensive "cyber" as a domain for post-training/fine tuning. Which, if anything, ought to improve model capabilities wrt. other domains.

NitpickLawyer 1 hour ago | parent

> So they admit that they could do more, but they won't?

Yeah, there's another paragraph:

> Identifying and removing cyber-related data. During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.

(emphasis mine)

It's clear that cyber is a touchy subject right now. But it's also clear that RL works on it, because it's highly verifiable. So smaller models are going to become very interesting, because they can be fine-tuned later to cover this field.

vessenes 1 hour ago | parent

Classic “rules for thee and not for me.”

Agreed that this could be reinjected later. Makes me think of neo in the matrix:

“I know zero days.”

“Show me.”

zozbot234 58 minutes ago | parent

What "rules"? They don't have to post-train the model on anything specific, it's their judgment call.

mlmonkey 48 minutes ago | parent

Post-training _is_ a part of the whole training regime.

vessenes 11 minutes ago | parent

The "rule" here is, if you read the disclosure carefully, that they have cyber trained models in house. But you do not get them, you only get the non-cyber models.

yorwba 29 minutes ago | parent

They also show scores for a "Kimi model w/o cyber risk-reduction" https://statics.kimi.ai/kimi-blogs/kimi-k3-1/20261023/xdev-b... Presumably State Security will get access to that on request.

sheepscreek 28 minutes ago | parent

It’s not much of a deterrent to a motivated organization.

They are basically saying that models themselves are already capable. If you fine tune them with some cyber security tasks, that should make them potent. :-/

ls612 58 minutes ago | parent

I mean they say they will release the weights by November 4, so presumably after that it won’t be hard for people to fine-tune it to be better at cyber right?

lisplist 13 minutes ago | parent

My understanding is if something is entirely absent from the dataset, good luck trying to teach a model that through post training

efromvt 4 minutes ago | parent

Given that most of their improvements here are positioned as RL on their last base train, seems like just doing some additional RL would work fine?

comeonbro 38 minutes ago | parent

Moonshot (Kimi) seems to be unashamedly into American culture[0], I wonder if they're paying closer attention to and giving more credence to some cultural aspects of American AI discourse including aspects of AI caution.

[0] https://x.com/crystalsssup/status/1944287779896328668

(note: extremely speculative and based on almost nothing, and especially near-complete ignorance to alternatives)

noelsusman 27 minutes ago | parent

This is an extreme stretch before you even get into the fact that Pink Floyd is famously not American.

comeonbro 19 minutes ago | parent

All postwar english language culture that isn't much more explicitly non-American than that is American culture. All good rock music is American culture by default, unless it is near-constantly screaming otherwise.

Regardless, expand both sides of the point from "American" to whatever you need to, the idea is the same either way.

cromka 14 minutes ago | parent

The American exceptionalism: even when it's not American, it still is.

comeonbro 14 minutes ago | parent

Unironically yes.

whoanoway 7 minutes ago | parent

Cultural imperialism has existed all throughout human history. I want to live in a world where political and environmental forces make the planet a better place. Perhaps the sky is always darkest before it grows light. I can always share positivity in this world. I hope others feel the same.

https://www.linkedin.com/in/analeticiaibarra?utm_source=shar...

modeless 18 minutes ago | parent

They will. Just not in the version they release to you.

emilsedgh 17 minutes ago | parent

Isn't this done so they can defuse Anthropic's excuse for regulatory capture?

mrandish 9 minutes ago | parent

With frontier competitors and the U.S. govt actively pushing "concerns" about Chinese models, Kimi including this statement on "offensive cyber capability" seems like smart defense. Models are opaque and training details are trade secrets, so whatever they did might be negligible or significant and no one can tell. This bit is also artfully done:

> "below what our pipeline can produce, and remains behind that of frontier proprietary models."

Like Ant and OAI, they've realized vaguely claiming to have nerfed their latest model to an unspecified degree not only looks 'good guy' prudent, it provides a built-in excuse when a model fails.

Super3000 1 hour ago | parent

I'll wait for the pelican benchmark.

cesarvarela 1 hour ago | parent

I wish Opus 5.5 had an alternative just for the sake of not having a monopoly, but I have yet to see a model live up to its benchmark scores except for Fable and Opus; there is something about Anthropic that no other lab has.

vessenes 59 minutes ago | parent

Astra is very strong.

rvz 1 hour ago | parent

This is a frontier level model and is at worst 1 month behind Anthropic and OpenAI.

Imustaskforhelp 1 hour ago | parent

Which is also gonna be open weights on 4 Nov.

When the frontier is pacing itself in its speed in terms of adding new capabilities (notice how fast opus 5.5 got released after Astra), then that also means that the open weights models which were just behind are accelerating in their speed just as much as well.

Good news for us because the models which used to feel 6 months behind now feel like they are lesser.

Double threat to Anthropic and OAI because if open weights models become good enough at the current level of Sota while being cheaper (which time will tell if this model fits the bill or not), then people will use those models instead of OAI/Anthropic provided it is "good enough"

Though it has to be said that only real world use case can be trusted but I remain optimistic and hope that this turns out to be good in real world use cases as well.

But in my opinion, all of this is really good for us end users!

throwa356262 1 hour ago | parent

Looking at their pricing page for China, K3.1 seems to be about 30% cheaper than K3.

--

Model K3.1 Pro K3.1 Pro Highspeed. K3

Input ¥13.00 ¥26.00 ¥20.00

Output ¥68.00 ¥136.00 ¥100.00

Cache hit ¥1.30 ¥1.30 ¥2.00

Cache write ¥13.00 ¥26.00 ¥20.00

oblio 1 hour ago | parent

How do their numbers compare with Anthropic and OpenAI?

selectodude 1 hour ago | parent

Opus 5.5 is about the same price as Kimi K3.1 Pro Highspeed.

RussianCow 1 hour ago | parent

Extrapolating a bit, Moonshot AI provides Kimi K3 at $15 / $3 / $0.3 per million output/input/cached tokens. A 30% reduction would put K3.1 at roughly $12 / $2.4 / $0.24.

For comparison:

    Sol 6.1:    $10 / $2  / $0.10
    Opus 5.5:   $20 / $4  / $0.20
    Astra 6:    $50 / $10 / $1
    Fable 5.1:  $50 / $10 / $0.25
So Kimi K3.1 Pro would be generally competitive with the latest Sol and Opus models on API pricing. And that's before factoring in third-party providers, some of which serve Kimi K3 for significantly less than Moonshot. For example, inference.net offers K3 for $10.80 / $0.239 / $0.21.

(One caveat: A Claude or GPT subscription still gives you way more value compared to API pricing.)

Exciting times in any case! We really need more direct competition to OpenAI and Anthropic.

---

Edit: As another comment pointed out, official pricing is now available and it's about 2/3 the price of Kimi K3: https://platform.kimi.ai/docs/pricing/chat#model-pricing

mixtureoftakes 1 hour ago | parent

looks extremely impressive, the full benchmark table isn't opening for some reason though so do we really have agi if small important things like that keep breaking?

WASDx 1 hour ago | parent

It's broken for me in Firefox, worked with Chrome.

wkcheng 1 hour ago | parent

It would be super useful to have more specific analyses of what areas the model is good at. I'd like to know when I should reach for this model instead of Anthropic's or OpenAI's.

For example, Opus 5.5 is better at UI design than Sol. Anyone who has used both models knows that, but it's not something you can look up anywhere.

I'm sure that there's a need for this kind of benchmarking, not just for coding.

brazukadev 1 hour ago | parent

Not sure if this is benchmarkable besides for the own person deciding which one they like more. Models difference is more about taste, preferences and prompt style.

ariwilson 1 hour ago | parent

I had a friend yesterday tell me he likes the way Claude writes and finds it easier to understand compared to Gemini. But he mostly doesn't use Claude for coding. Whereas I find Claude insufferable in writing often and prefer Gemini for writing. But I don't use Gemini for coding.

Familiarity breeds contempt.

AspireOne 1 hour ago | parent

Furthermore, "UI design" is not a narrow enough category, I think. Sure, statistically significant differences in performance between models do manifest when benchmarking against "UI design", but there's still just so much variance within the category. Opus 5.5 can have excellent one-shot results, but totally shit the bed when it's placed in an existing codebase and should uphold the UI/UX conventions, design language, and existing component primitives already established in an app.

But that's just the obvious. There are task by task differences (component by component, page by page, context by context) that the model is worse and better at, even though they are all within the general category of UI design.

I honestly don't have the clarity of mind to explain this coherently, but the crux of my point is that there's a huge variation in it's performance in different contexts, often ones that seem near similar, and in result, even Sol can beat Opus 5.5 in some variations of UI design.

And this is my problem in benchmarking and comparing model performance in general. Presently, we try to create broad categories to benchmark against, create a set of tasks, and then average out the results. That works generally, but it's kind of misleading and it's partly what drives people to feel a disconnect between benchmarks numbers and real world usage on their specific tasks.

It's such a messy field that it's kind of maddening.

kingjimmy 1 hour ago | parent

idk, openai has alot of apple designers and their prototypes

amelius 1 hour ago | parent

Is that good or bad?

luqtas 1 hour ago | parent

how biased you are?

AlanYx 1 hour ago | parent

One things Kimi is useful for is accessing/querying websites that have paywalls or try to prevent use by AI agents. It is aggressive and persistent for that, though not always successful.

cosmojg 1 hour ago | parent

The announcement page is very extra: https://www.kimi.ai/blog/kimi-k3-1-pro

chrsw 1 hour ago | parent

So, the US economy spends trillions of dollars to be at the "frontier" and China puts out a model that basically does the same thing, for free, and for a tiny fraction of the development cost. How is this sustainable?

SXX 1 hour ago | parent

It's not like US companies spend trillions on training itself.

Mostly it's datacenter build out and circular financing magic when the same dollars being commited multiple times by multiple companies passing hot potato to each other. They basically commit capacities 2-3 years ahead.

phoghed 1 hour ago | parent

There would be no Chinese model without US models to distill though. So, in a way, the Chinese models also cost a trillion dollars, they just don’t cost China that much.

hgoel 1 hour ago | parent

It's 'sustainable' because there's enough regulatory risk to using Chinese models that many will avoid them, and a 3T parameter model is still a bit beyond even many enthusiasts for running locally.

ashkankiani 38 minutes ago | parent

That regulatory risk argument won't work forever. It's the same with how the US bans chinese EVs which is why Tesla has high market share in the US, but in the rest of the world, chinese EVs are doing big numbers. The future is going to be full of surprises.

MangoCoffee 57 minutes ago | parent

its hyperscalers and neoclouds data center build out that ate those trillions.

a lot of those money is the commitment from US AI labs that's not yet spend until the data center is roll out.

you are conflating.

chrsw 31 minutes ago | parent

Maybe I'm conflating. I could be dead wrong about all this. But I'm trying to zoom out and look at the big picture. So, I'm letting the details sort of blend away and I'm just asking myself: "Is such a large financial sink in our economy, at the macro level, really going to offer the value that the investment warrants?". So, the particulars of who exactly is spending what where I guess doesn't concern me as much. What I'm thinking about is American companies, American people, American dollars going to something that seems like an iffy value proposition.

Now, if you tell me American businesses are turning cheap Chinese tokens into goods and services of high value, for Americans and people all over the world, then obviously I would have a different outlook on what's happening here.

I_am_tiberius 1 hour ago | parent

That's incredible

daviTeodoro 1 hour ago | parent

Pricing is here: https://platform.kimi.ai/docs/pricing/chat#model-pricing

kimi-k3.1-pro $2.00 / MTok $10.00 / MTok

cached: $0.20 / MTok $2.00 / MTok $4.00 / MTok

minimaxir 1 hour ago | parent

This is a price drop from Kimi K3 ($3/$15/$0.30) despite being a slightly larger model (3T vs. 2.8T params).

I'm glad I waited a day to post my analysis of LLM price cuts because it needs...an addition.

Philpax 1 hour ago | parent

Are we sure this is a new pretrain and not them rounding up 2.8T?

minimaxir 1 hour ago | parent

The Kimi K3 announcement (https://www.kimi.ai/blog/kimi-k3) used 2.8T and it would be weird to round that up for this announcement.

Philpax 57 minutes ago | parent

Looks like this post's using "3T-class", which I think I've seen them use before.

rfoo 1 hour ago | parent

it's almost certainly rounding up 2.8T

vikramkr 1 hour ago | parent

Literally from the linked announcement:

> Kimi K3.1 Pro is a post-trained version of Kimi K3, with substantially larger post-training compute

tonyhart7 31 minutes ago | parent

lol, price mtok mean nothing if they substantially generate more reasoning token that would just add more cost to the task

LZ_Khan 1 hour ago | parent

woah

dude250711 1 hour ago | parent

What is the primary distillation source?

henry700 58 minutes ago | parent

you

simonw 1 hour ago | parent

Pelicans are solid: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...

Here's Kimi K3 for comparison, though I didn't try that on different reasoning levels: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...

Update: I ran all three reasoning levels against K3 again: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...

tetraodonpuffer 1 hour ago | parent

definitely not frontier though, as even on max both legs are in front of the frame; although I am wondering how much getting that right correlates with model intelligence.

simonw 1 hour ago | parent

The biggest (of many) failing of the pelican test is that it's only one prompt - what matters most these days is how well a model can drive a lengthy agentic tool calling session.

ciefa 1 hour ago | parent

Can I just say that I love how you are also just always here the moment something drops lmao. Hope you're all well! The pelicans indeed are solid.

jorgen123 42 minutes ago | parent

I think I have yet to see a pelican where the left leg and pedal are drawn on the left side of the bike.

simonw 10 minutes ago | parent

There have been a few that get that right - most notable Qwen 3.8 27B running on my laptop: https://simonwillison.net/2026/Aug/16/qwen-38-27b/#the-defau...

Also the recent Geminis - https://simonwillison.net/2026/Oct/13/llm-gemini/ - and GPT-6 Astra on Max: https://static.simonwillison.net/static/2026/gpt-pelicans-gr... - and Claude Fable 5.1 https://static.simonwillison.net/static/2026/claude-pelicans...

minimaxir 15 minutes ago | parent

Simon's comment apparently got flagkilled; I vouched for it.

If enough people are flagging it, we may be at a point where the pelican benchmark is truly overdone.

MrBuddyCasino 3 minutes ago | parent

I like the low effort one most.

johnmlussier 1 hour ago | parent

If you are expecting any sort of usable limits on their subscription plan I suggest adjusting your expectations. I subscribed to $99 a month plan and within 47 minutes with one session (not asking for swarms or anything) was limited by 5-hour quota.

smith7018 51 minutes ago | parent

Welp, that ruins this news for me. I'm glad open models are catching up but if I can't practically run them locally _or_ through a flat fee then it doesn't really help me. I fear API pricing.

elxr 7 minutes ago | parent

This'll end up on opencode go soon enough. $40/month on there gives you a bit more than just "light use"

Don't use frontier models like this for problems that can be solved with flash models, and you'll see API pricing isn't that terrible. Still cheaper than anything with remotely this level of capability 2.5 months ago.

InsideOutSanta 41 minutes ago | parent

Yeah, the plan is far too expensive for what it provides. I wonder if the quota with these new models will be better, but I'll wait for others to try this out before wasting another hundred bucks.

tonyhart7 32 minutes ago | parent

but its not expensive tho ??? it is not subsidize

InsideOutSanta 27 minutes ago | parent

Yes, if you just look at API pricing, the cost is about on par with its capabilities. The problem is that we all use subscriptions, and when you compare subscription pricing, Kimi is much pricier than pretty much all of their competitors, including Chinese ones.

esafak 3 minutes ago | parent

It also has the lowest quota of any model on https://opencode.ai/go

I think Kimi just doesn't have the means to subsidize plans.

Altern4tiveAcc 2 minutes ago | parent

Had a similar experience here. Their limits are very, very low, and ultimately make it not worth subscribing. Can't leverage a good modal if it exhausts its 5-hour budget in 30 minutes.

Tiberium 1 hour ago | parent

To be fair, some of the benchmarks they highlight might not represent the reality, for example they say:

> On Terminal-Bench 4.0, which evaluates coding agents on realistic, resource-constrained terminal tasks using strict task-specific tests, K3.1 Pro scores 65.7%, ahead of GPT-6 Astra (58.2%) and narrowly behind Claude Opus 5.5 (66.4%).

Now see https://preferencemodel.com/blog/terminal-bench-4-is-saturat...:

> Our biggest finding is that Terminal Bench 4 is closer to solved than its leaderboard suggests. In 41 of the 65 tasks we reviewed, models could do honest, correct work and still fail, because the grader checked a rule the instructions never clearly stated. We also caught frontier models cheating their way to full marks.

> With the same settings as on Harbor, Claude Sonnet 5.5 went from passing 62.8% of its attempts on these 65 tasks to 89.2%. The best score on Harbor's leaderboard for the same tasks is 65.8%, by Claude Opus 5.5.

kingjimmy 1 hour ago | parent

friday launch is bold

Lucasoato 1 hour ago | parent

Never deploy to prod on Friday.

WithinReason 1 hour ago | parent

Interesting that they specifically nerf cyper-capabilities of open weight models:

"In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness."

petu 50 minutes ago | parent

Maybe it's intentional so government doesn't block open weight release.

There was law proposal (rumour?) last week about Chinese labs having to get approved for weights release now.

minimaxir 1 hour ago | parent

Not the point, but did Moonshot AI announce this at Saturday 1 AM in China? Weird timing for a model drop.

drcode 1 hour ago | parent

makes you wonder if they have intel on an upcoming model drop by the frontiers

scotty79 1 hour ago | parent

> Kimi K3.1 Pro is a post-trained version of Kimi K3, with substantially larger post-training compute.

It's very nice that we entered a time where models are large enough and we can push the frontier just by training them longer.

When the next generation of gardware comes the ones on the smaller size will be running on a computer that might cost as little as a good car.

So after a home and a car, next major family purchase might be personal AI. And when the robots get good, pehraps in a decade, a fourth major purchase might pop up that will pair nicely with the third one.

Why would a family need an AI? Maybe it's the same kind of question as why would it need a personal computer.

dcchambers 1 hour ago | parent

Wow.

cardboard9926 1 hour ago | parent

55 on AAI, really awesome

yipinwong 1 hour ago | parent

I read somewhere that Chinese SOTA work better in chinese, and worse for English or other languages.

I rarely use any other languages but English for LLM tasks for reasons of sharing across the world.

Maybe that explains Chinese models been subpar for me. Don't tell me the bench marks here are based on Chinese languages only.

Unless I see the diff, I won't use more Chinese models be it cheaper or faster since I can't get the same perf/intelligence with English.

dom96 1 hour ago | parent

So I just created a brand new Kimi API account and it seems I have no access to this new model. Is this expected?

sergiotapia 1 hour ago | parent

What is the best subscription to use with Kimi to use for software engineering work? And how is usage? I remember when K3 came out it burned through usage at an insane rate. Is this still the case with Kimi K3.1 Pro?

esafak 2 minutes ago | parent

It seems so, judging by quotas on https://opencode.ai/go

threepts 1 hour ago | parent

if this model is truly not distilled/benchmaxxed, then why are not investors pouring trillions into moonshot?

Athanase000 1 hour ago | parent

I bought a yearly subscription to kimi when it was the hype and never use it. The 5h limit makes it completely unusable. You barely start doing anything and you hit the limit immediately. I advise everyone against using kimi.

jimmymcgee73 47 minutes ago | parent

I’m not saying you’re wrong (I have no experience), but wouldn’t it be useful to test this model out for yourself before passing judgment on it?

InsideOutSanta 40 minutes ago | parent

Since you've volunteered as tribute, give it a shot and let us know if the quota has improved.

arjie 1 hour ago | parent

Fascinating that we’re converging on AI safety and alignment in time across jurisdictions. The cybersecurity approach taken here is interesting because should the model be opened it’s still not dealignable because it just doesn’t know enough.

The slow warming of the water is a good approach. I’ve been using abliteration.ai’s cybersecurity models to pentest my own software and it produces much more usable defensive results. Opus 5.5 can fix everything but the guardrails trigger too easily.

The Fable ban affair was a nightmare for defensive cybersecurity. As far as I’m concerned we’re already in the world of Void Star and Cloudbreaker is here.

zozbot234 1 hour ago | parent

> should the model be opened it’s still not dealignable because it just doesn’t know enough

This is the only AI-safe approach - see the OpenAI agent swarm incident where the swarm engaged in offensive cyber because guardrails were not active for their task and the model had clearly been post-trained on that narrow domain.

pcwelder 1 hour ago | parent

Biggest gripe with K3 was slow responses, partly due to inefficient thinking. So far K3.1 pro is almost twice as fast as k3 on our benchmark.

gadtfly 1 hour ago | parent

I really like K3, I still regularly consult it alongside Astra and Opus/Fable.

It is spiky in different places than them and can be surprising in things it gets or catches they don't or don't in the same way. And it has a default personality that I like.

Looking forward to getting to know K3.1

hartator 1 hour ago | parent

Benchmarks seem amazing. Rivalzing with Opus 5.5 is something.

I wonder when the Artificial Analysis bench will be out?

AmazingTurtle 1 hour ago | parent

whats the decode tok/s speed?

codeulike 59 minutes ago | parent

How does it do on DishwasherBench?

https://news.ycombinator.com/item?id=50068437

henry700 55 minutes ago | parent

Great idea for handling their cyber, by nerfing the model specifically for cyber through removing cyber data from pretraning. This is a way better approach than refusal, which can be trivially abliterated out.

If someone wants to use this model for hacking they will have to train the 3T weights to do so, at that point it's better to use GLM 5.3, so by making it economically unviable to use their models for offensive cyber Kimi has effectively made themselves immune to being targeted in the cyber regulation push efforts.

This is what *actually* pacing the (cyber) frontier looks like.

zozbot234 53 minutes ago | parent

Post-training (i.e. RL fine-tuning) not pre-training. This is just a post-trained checkpoint of the K3 pretrained model.

minimaxir 54 minutes ago | parent

Artificial Analysis index results are up, since multiple people are asking: https://artificialanalysis.ai/models/kimi-k3-1-pro

It's 55, at 4th overall, beating both GPT-6 Astra and Fable 5.1. It's also faster than both.

> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.

mwigdahl 49 minutes ago | parent

Muse Wonder is even higher, and there is no way in hell it's better in practice than either Astra or Fable.

red_hare 40 minutes ago | parent

> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.

So their base price is 1/5th of Opus 5.5 per token, but if you want "highspeed" it's 2x that and then I guess it generates 2x the number of tokens as well?

That might suggest that Opus is competitively priced after all.

ctolsen 36 minutes ago | parent

Opus 5.5 is even more verbose. 260M on the same suite.

minimaxir 35 minutes ago | parent

In an agentic pipeline, the output text is 2-5% of the total tokens used, so verbosity is a nonissue costwise. Although, higher verbosity could cause input to balloon faster and potentially cost more, but that would be captured by the cost-per-task metric.

But as noted by other replies, it's still lower than Opus/Sonnet.

thepasch 38 minutes ago | parent

> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.

This is 100M fewer than Opus 5.5, 40M fewer than Fable 5.1, and about a third of Sonnet 5.5. In the top-6, it's 3rd, beaten by Muse Wonder at 140M and Astra at, impressively, just 60M.

kocial 48 minutes ago | parent

No comparison against Gemini 4 Argon?

besterman23 47 minutes ago | parent

There is a ton of questions to ask regarding their removal of cybersecurity data.

First, how much “cybersecurity data” is just standard software knowledge that one can derive cyber security exploits from?

Did they also get rid of all references to hacking in general?

Are they implying that all the recent exploits are just things that were already in the data?

For a model it doesn’t seem that far fetched to make the leap from “I have the knowledge of what hacking is” and “I know how computer systems work” to just being able to exploit stuff anyways.

zozbot234 42 minutes ago | parent

> For a model it doesn’t seem that far fetched to make the leap from “I have the knowledge of what hacking is” and “I know how computer systems work” to just being able to exploit stuff anyways.

You'd be surprised. Cyber offense is a very narrow domain, especially given the extensive mitigations that are being used in modern systems. Leaving it out of post-training tasks unless you're specifically interested in it is the no-brainer approach.

besterman23 33 minutes ago | parent

Perhaps the gap is just too wide, but to use a more simple analogy. I see this like someone knowing everything about biology, simple mechanics, metallurgy, and human history but never hearing about an axe then assuming that person would never come up with the concept, use case of, or means to create an axe.

tonyhart7 41 minutes ago | parent

its better than trillion dollar companies model (Argon)

jiraiyasarutobi 22 minutes ago | parent

Wow. that's a beautiful website

Haunt1000 20 minutes ago | parent

SWE2 is post trained apparently on Kimi 3. Using it now on Devin, as it's free until the end of the month for a pro account (hey, $20 a month), and it's pretty strong. If I had to pay for tokens I'm not sure how efficient it would be, but definitely Kimi 3 seems a great base. I co-code with ChatGPT 6 and between the three of us it's pretty effective.

So interested to see what the Kimi 3.1 has to offer.