90 points dbreunig 2 hours ago 80 comments

dizhn 1 hour ago | parent

It's NES

someperson 1 hour ago | parent

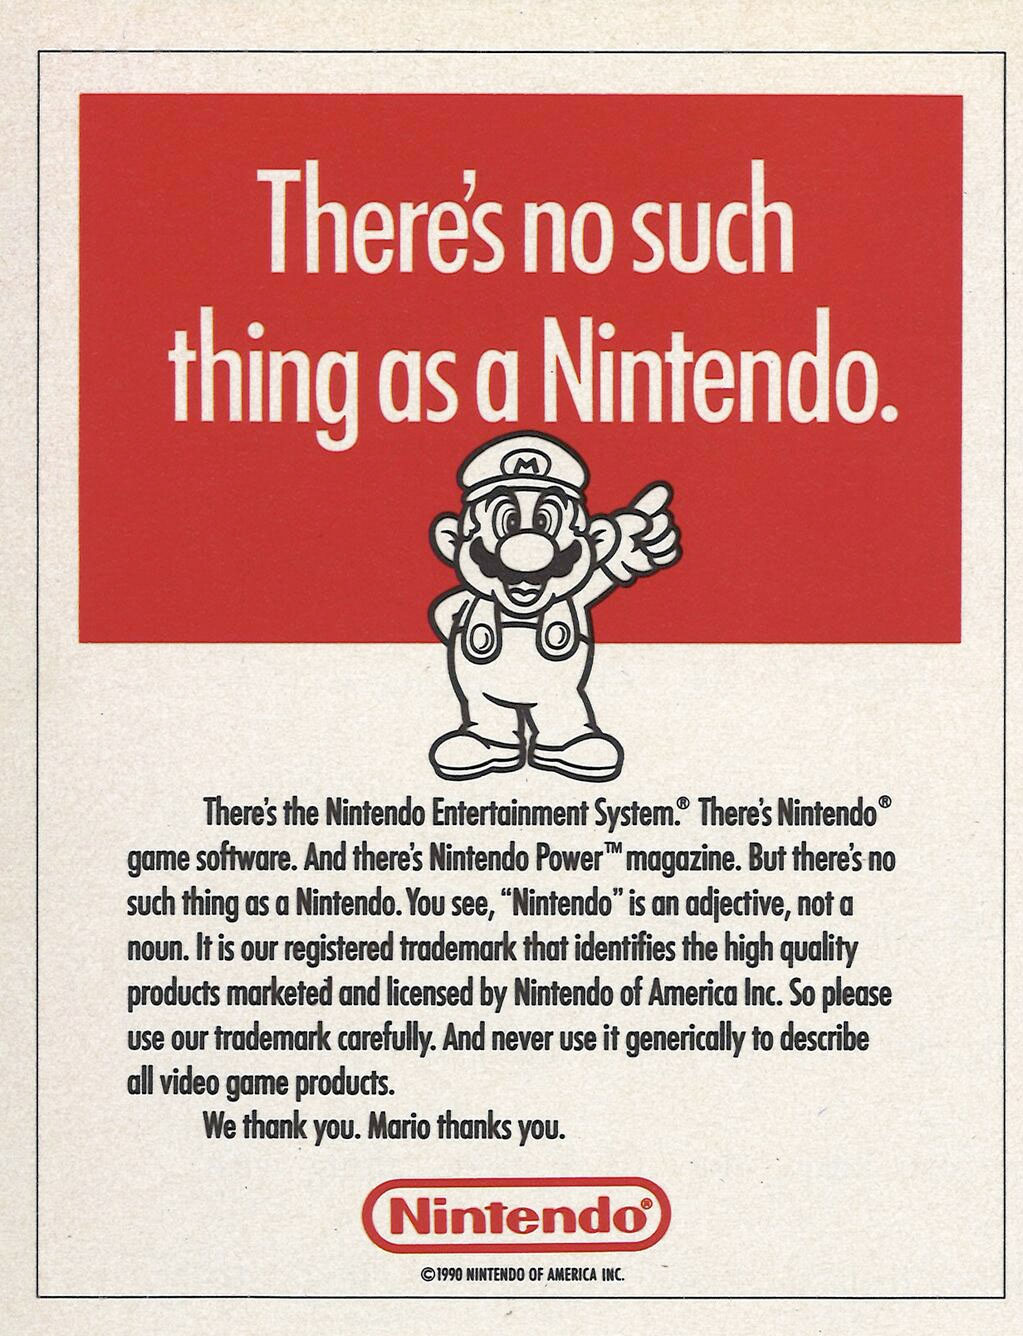
Yes, calling a Nintendo Entertainment System (NES) a "Nintendo" may have made sense in 1989 or 1990, but not in 2026.

dudeinjapan 1 hour ago | parent

TBH I think classic Mario when I hear "Nintendo". The new stuff is a Wii or a Switch. Granted I was born in 1984.

piker 1 hour ago | parent

Same, same and same.

ranger_danger 1 hour ago | parent

They were really upset about it even back then: https://gcdnb.pbrd.co/images/9zn32PxVXM5w.jpg

rtkwe 1 hour ago | parent

The title is very "grandma who doesn't know the tech" coded. Every game system is the Nintendo, controllers are remotes, etc.

jacquesm 1 hour ago | parent

I love these hacks, even though from an efficiency point of view it is horrifying to my assembly-code-golfing-brain. And it also gives some new appreciation for how much more efficient deterministic programs are compared to AI.

nonethewiser 1 hour ago | parent

The day is coming when we have widespread local inference on super powerful and efficient hardware and people will ask it what time the store closes, get distracted, and then ask it again instead of scrolling up.

jacquesm 1 hour ago | parent

That probably has already happened.

carljungslabtek 1 hour ago | parent

I’m ashamed to admit I do this on my work account sometimes… Not for looking up a basic fact of course.

I wish they would let me use claude desktop, I really hate looking at the terminal and don’t know how to customize it to make it more readable

tmpz22 1 hour ago | parent

> I really hate looking at the terminal and don’t know how to customize it to make it more readable

On a comment where you discuss a powerful tool for looking up information, you claim ignorance about a piece of information that same tool could explain to you! What the heck!

misiti3780 1 hour ago | parent

am i the only one confused by this ?

tomcam 1 hour ago | parent

I believe GP is making the point that tokens are expensive atm so we are better at conserving them (the scroll back part), but soon it'll be so inexpensive or even free that we won't bother.

misiti3780 1 hour ago | parent

tokens are not that expensive...

matthewsinclair 1 hour ago | parent

There’s another way?

bitwize 1 hour ago | parent

Once our compute base shifts from silicon to human brains grown in vats, you'll be thankful you can run all your old deterministic compute tasks on flesh neurons!

garciasn 1 hour ago | parent

Two years ago: nice toy.

18 months ago: it can do some things but it’s generally not useful.

12 months ago: wow; this can write ok code that a human has to do a lot of review to make sure it’s ok.

6 months ago: holy fuck I’m shipping great stuff with only the occasional redo.

3 months ago: Jesus Christ this is actually pretty fucking great. I have to work entirely differently; becoming a manager of my single agent launching sub agents.

1 month ago: my god I am shipping more, faster, and more useful than ever.

Today: we have fleets of highly effectively domain expert agents working entirely autonomously and shifting between fleets depending on domain, available usage remaining, and we’re shipping 10x with 100% better reviews than before—expanding by the day and self-improving its own harness.

—-

Next week: the agents will prioritize code golf.

The week after that: everything is written in ASM.

We’ll come full circle in 3y

e: fyi; this is my personal progression with LLMs.

jacquesm 1 hour ago | parent

Next week: hey, I'm out of a job, what happened?

tomcam 1 hour ago | parent

I think that's this week

pjmlp 1 hour ago | parent

This is what I don't get with the kind of posts you are replying to.

I have experienced directly what the evolution of cloud based software, and now AI based tooling, has done to team sizes on delivery projects.

Cannot understand how they don't get how all the performance improvements directly correlates to smaller team sizes, in shareholders driven economy.

So far I have been lucky, and just hope to have enough savings when time comes, as finding jobs after 50s wasn't already easy without having to add AI on top.

garciasn 1 hour ago | parent

Because I don't live in a world where my team needs to grow for me to feel more successful? My teams have been small and tight-knit at every place I've been an Eng leader. I left a job with 13 engineers and they're at >90 now, apparently doing less; but, that's just what I hear second-hand.

I want to do MORE with the same amount of folks.

jacquesm 35 minutes ago | parent

HR meeting in room #3, please bring your coat with you.

jacquesm 52 minutes ago | parent

I think it is because programmers are not that good at economy or running a business. Their bosses are though and they don't see a productivity tool, but a way to reduce their costs.

DANmode 12 minutes ago | parent

What about their comment says they don’t understand that?

Imustaskforhelp 1 hour ago | parent

> The week after that: everything is written in ASM.

This is an genuinely good minimalist good editor that is created in mostly assembly that was created with the help of AI[0]

I maintain a fork of it which basically adds scratchpad ability to it and is something that I use daily myself for what it's worth[1]

My fork was created with the help of GLM 5.3 (an open-weights model)

The future is already here in some sense. I could in theory add more features but I intentionally add not more features because asm is still slightly difficult for it to write but in some sense the tradeoff has been/could be worth it. It was more of an experiment really and I am really impressed by it.

in many ways, forcing AI to write asm does make you now think intentionally of features and ironically prevents feature creep and makes you think of stability of the product (atleast right now for me anyways)

[0]: https://rhun.app

[1]: https://github.com/serJaimeLannister/rhunpad

misiti3780 1 hour ago | parent

i wish this was my experience, it's basically the opposite. im shipping a little faster -- but spending endless amounts of time reviewing LLM-generated code that usually isnt production ready.

derwiki 58 minutes ago | parent

> The week after that: everything is written in ASM.

Also “1 month ago,” but s/ASM/Rust

amelius 1 hour ago | parent

How do they know it's "working"?

Did they test every possible input/output combination?

anyfoo 1 hour ago | parent

Do you test every possible input/output combination on any CPU?

No, because that would be impossible.

You perform a series of more specific tests. In this case, it's "working" in so far as that Super Mario Bros. appears to be playable, for example.

Does not mean that it behaves perfectly according to some spec, or identical to another CPU (like the NES's 6502), of course, but it's clearly a working CPU to some 6502-compatible extent.

dbreunig 20 minutes ago | parent

This is a case where we basically did test it on everything! Because the emulation community maintains conformance tests with over 3k of golden instructions. (And this is why Opus was able to so effectively build it; it found the tests)

anyfoo 11 minutes ago | parent

Yeah, but that still doesn’t mean there aren’t theoretical bugs. Testing every input would effectively mean testing every stimulus, which is combinatorially impossible. You might still have subtle timing bugs, bugs with very uncommon instruction sequences etc.

But my point was exactly that the (extremely vastly) smaller subset of tests that you performed is more than enough to proclaim a CPU to be “working”.

dbreunig 1 hour ago | parent

Doesn't work for all cartridges (I didn't run Opus that long, but it could keep going). Works with Super Mario.

But to answer your question, it's in the readme: https://github.com/dbreunig/nesformer#how-it-was-checked

WoodenChair 1 hour ago | parent

I guess I don't understand the point of this. Of course a set of digital logic circuits can be reduced to a set of weights. Am I missing something?

jacquesm 1 hour ago | parent

Not a climber then?

lucasoshiro 1 hour ago | parent

Because it's fun

WithinReason 1 hour ago | parent

Apparently it's news to some people. It also helps combat the "LLMs ArE nOt DeTeRmInIsTiC" complaints.

rvz 1 hour ago | parent

> It also helps combat the "LLMs ArE nOt DeTeRmInIsTiC" complaints.

Reality says otherwise, especially from those who run LLMs in production at a large scale. Hacks such as baking in the weights with tiny experiments doesn't disprove anything.

The same LLM boosters also continue to repeat one of the biggest misconceptions: "sEt TeMperaTurE tO zERo tO aChiEvE fUlL dEterMinIsm."

recursive 1 hour ago | parent

Doesn't help much

ansk 1 hour ago | parent

This work, and the original qwenputer work it builds on, are both technically uninteresting slop. HN eats it up though.

rvz 1 hour ago | parent

HN loves slop meetoo projects without questioning the details. With close inspection it is an overly complicated version of this paper [0] on neural turing machines.

This concept was hyped up (because DeepMind) for a while at the time and in reality it amounted to nothing. This is just the second reincarnation of a similar concept but with added extra saturated slop and hype on top.

[0] https://arxiv.org/abs/1410.5401

ansk 56 minutes ago | parent

That paper is great work. This qwenputer stuff is slop. The problem is that HN can't tell the difference.

igravious 56 minutes ago | parent

Sometimes projects have no point other than to show what can be done – and the pure thrill of doing is an end in itself … but I agree with you in the "so what" sense here … I feel like with this project there is meant to be a point (other than play for the sake of play and art for the sake of art and coding for the sake of coding) but I'm not seeing it either?

woah 1 hour ago | parent

This is like when people used to make tetris using only CSS or whatever in the 2010s. But it's less impressive because Claude Code can slop it out in an afternoon.

mlmonkey 1 hour ago | parent

Can someone give a TL;DR ? What's the input to the model? What's the output?

cafebeen 1 hour ago | parent

I expected this to only simulate the CPU itself, but was surprised to find they actually simulate the RAM as well (contained in the model itself via the gated deltanet architecture). So in my understanding, the CPU, ROM, and RAM are all handled internally by the model, and the only inputs after initialization are the controller events, wild.

dbreunig 22 minutes ago | parent

This has the nice side benefit of letting the 1gb of weights compress down to ~3mb (since it’s mostly empty)

creposukre 1 hour ago | parent

Omg what is this sorcery?!

pbohun 1 hour ago | parent

>Overall, nesformer runs 150–290× slower than the real console.

I like these kinds of projects because it helps to show the massive compute requirement between LLMs and ordinary programs.

A while back I saw some people saying we would just have LMMs hallucinate an entire operating system every single frame. I guess technically it's now proven to be technically possible, but it would be thousands of times slower while requiring thousands of times more compute (a multi-million x difference from an ordinary OS!).

varispeed 1 hour ago | parent

Isn't that the same with e.g. human brain? Computer program can compute billions of equations, whilst human will struggle with just one.

Terr_ 1 hour ago | parent

Perhaps, but it doesn't indicate anything new or interesting about cognition or biology.

For example, Minecraft in Minecraft [0] is (while impressive) slow and inefficient too, but it doesn't tell us much about humans except that some of them are weirdly ambitious in their projects.

[0] https://www.youtube.com/watch?v=-BP7DhHTU-I

krige 1 hour ago | parent

Human brain does a lot more at any given time than just whatever you're consciously thinking about.

jagaerglad 51 minutes ago | parent

The ones we're not thinking about is the computer program abstraction layer in our brains. I think consciously thinking about an equation in our brains is the LLM layer equivalent, we're reasoning about it with language logic or models of our spatial senses (the unconscious calculations)

im3w1l 1 hour ago | parent

These systems in weights are proof of concepts. Surely there is room for optimization in there somewhere.

jerf 1 hour ago | parent

Yes, there is.

It's called a Nintendo emulator.

That's kind of the point here.

Code isn't going anywhere. It can be literally billions or trillions of times more efficient than an AI, and as AIs scale up that number just continues to grow and can completely plausibly hit quadrillions in our lifetime. What relationships humans have with code is a completely different question, but the idea itself isn't going anywhere. Anyone who thinks otherwise has failed to grasp just what producing a single token from an AI actually entails.

pishpash 43 minutes ago | parent

It would be baking the model into hardware or FPGA, which ends up building the same thing being emulated. An emulated ALU in hardware is ... the ALU.

jedbrooke 53 minutes ago | parent

This is a bit different though. It’s using transformer architecture to emulate almost at the circuit level. It’s probably even more inefficient than something that was trained to emulate a cpu, but with the advantage of actually being an exact emulation rather than learned approximation.

It’s a bit like when a human brain remembers facts, if you sat down and computed the hash values of the thing you were trying to remember, and traced out a DB lookup in your mind, it’d be a lot slower than just “oh yeah I remember that”.

btown 23 minutes ago | parent

We're in a really interesting world where "anything can run anything." Like, in theory, you could get Doom to run on a Cerebras that's specifically laid out for $specific_model architecture, by swapping the weights it holds in SRAM. Just like we're currently running $specific_model on GPUs that were designed for games in the first place.

To misquote a certain YouTuber: LLMs are just games, unlimited games, but no games.

acedTrex 14 minutes ago | parent

How accurate is that run of doom i wonder is it lossy in any sense

barelysapient 53 minutes ago | parent

That's the case right now--but what might a customized model tailored only for a narrow set of OS functions behave like? I suspect its achievable with a lot less compute.

Now is that a desirable product? Would it succeed on the merits in the marketplace? Maybe it would...

pbohun 42 minutes ago | parent

As an example, is it faster to multiply 2 numbers using a single MUL instruction or multiply matrices with millions (or billions) of elements multiple times? Multiply that overhead by every single thing you do and that's the overhead of using an LLM to emulate a program.

augment_me 47 minutes ago | parent

Let's say you are developing a product, choose 1:

1) Have a single person vibe together a computationally inefficient solution in 1 month that runs transformers on some backend.

2) Hire a team to work for 2 years to design, perfect, optimize, plan, revise, and architect a solution.

The risk/reward for 1) is extremely better than 2). Given the turnover for entertainment in this day and age it doesn't make sense to do all this complex stuff.

suddenlybananas 43 minutes ago | parent

You can't generalize and say that 1 is better than 2, it depends entirely on what you are developing, for whom and for what purpose. For a one-off dumb thing for a few people 1 is fine, for anything at scale, 2 is likely better.

pbohun 41 minutes ago | parent

It would be much better to use LLMs to create ordinary programs than to use an LLM over and over to emulate something that's thousands or millions of times more efficient.

dolni 4 minutes ago | parent

Thousands or millions of times less energy used is a whole lot better for the environment, too.

pfisch 26 minutes ago | parent

How do you vibe a transformer solution without the existing real solution, which would be needed to generate the training data.

These are just machines for ripping off existing games/programs with mostly accurate simulations. You can't vibe together a transformer of something that doesn't exist with meaningful control over the results.

pasquinelli 24 minutes ago | parent

> Given the turnover for entertainment in this day and age it doesn't make sense to do all this complex stuff.

are we not talking about the NES?

ant6n 26 minutes ago | parent

It would be a natural extension of the current work in software. Every layer of abstraction/web/scripting language adds seemingly 10x in both ram and processing time, undoing the advancement of 1000x faster processors and ram increases.

But at some point we’re hitting a wall here. If we want our software to undo 100,000x more processing powers, we need that llm software emulation layer.

woah 18 minutes ago | parent

This is exactly like if someone implemented a CPU using nothing but CSS animations. Maybe a fun way to teach about turing completeness, but pretty meaningless otherwise.

not_a9 13 minutes ago | parent

touristshaun 12 minutes ago | parent

Hard disagree on it being meaningless. Just showing that this is now possible and providing the details on how it was accomplished makes it invaluable to builders.

ben_w 10 minutes ago | parent

> A while back I saw some people saying we would just have LMMs hallucinate an entire operating system every single frame. I guess technically it's now proven to be technically possible, but it would be thousands of times slower while requiring thousands of times more compute (a multi-million x difference from an ordinary OS!).

Gosh. That would be a very silly use of an LLM.

Bad use of any AI, even image/video models which are certainly less wrong than this. Stuff like DLSS show we're getting stuff that could generate a game's graphics frame-by-frame, but even though it's possible to have an entire game environment (not just graphics, everything) done by an AI, such things demo better than they play due to temporal coherency.

That said, having an AI make the code for each thing as you need it, might work somewhat OK eventually. Wouldn't trust it today (security, data integrity, and a tendency to cheat on tests), but eventually it could happen.

armcat 1 hour ago | parent

This opens up so many interesting opportunities. In principle one could compile a small VM inside the LLM weights. The VM can host for example a Python interpreter, a shell and tools like sed, cat, grep etc. Instead of LLMs having to do slow autoregressive token emission with the current "external" tool calling, it could literally execute everything except web search, inside the LLM, with just matmul operations. You could probably optimise this so it runs in batches. You could have a gdb like application that can step through the LLM forward pass. Anyway, just a crazy thought. Have a great weekend everyone!

kirubakaran 10 minutes ago | parent

munro 1 hour ago | parent

Woowww this is cool, not trained is even cooler--maybe I'm probably a bit naive, but to me it demonstrates an understanding of how an LLM can compute

dbreunig 1 hour ago | parent

A couple thoughts on the process here…

First off, Opus 5.5 built working weights and code with only two prompts:

1. Read this article and any relevant source code: https://divagr.com/blog/qwenputer. Then explore if you could emulate the chip and ram in a Nintendo Entertainment System (as people do today with FPGAs in MISTRs) using this technique. If so, what size model would you have to build and if you could use smaller faster ones, could you get it to be at the standard clockspeed.

It returned charts well illustrating any model would be _slow_. But it's still fun, so the second prompt was:

2. I think we should build it! Just for fun. It's okay if it's not fast. We want to be able to have the weights, and a cli to run them that we can point at a ROM.

Now while this was an _epic_ run by Opus (5.5 is a crazy capable model), this is a surprisingly well-structured challenge.

There is a long-lived and incredible community of classic gaming emulation work online for it to reference. And that community has created…conformance tests! Opus found them and built against one, that has >3k golden instructions: https://github.com/christopherpow/nes-test-roms/blob/master/...

Also, there is the original Qwenputer repo that Opus used to drive the weight writing. That was essential.

But this is a great example of what these models can do with proper reference materials, great specs, conformance tests, and clear direction.

cadamsdotcom 51 minutes ago | parent

Truly amazing. Quite thought provoking how it was helped by having high quality oracles. Eg. Qwenputer & good NES reference materials.

I guess humans need their oracles too: teachers, encyclopaedias, degrees, phds.

Bravo, awesome project, really creative!

nico 48 minutes ago | parent

> nesformer builds on Qwenputer by Divyansh Agrawal, which compiled a CHIP-8 and then a RISC-V CPU into Qwen3.5-4B. It reuses Qwenputer's compiler and its central trick: the model's Gated DeltaNet state is the machine's memory

This is amazing, love it! Qwenputer is very cool too

akie 18 minutes ago | parent

I'm guessing it's safe to say that LLMs can run Doom.

vorticalbox 8 minutes ago | parent

Has anyone tried training a diffusion model for speed ?

lachlan_gray 8 minutes ago | parent

It mentions a greedy decoder in the readme, I'm curious what would happen if you run it stochastically with T>0. Vibe NES? Or does it just crash.