196 points lairv 8 hours ago 599 comments
shmoil 7 hours ago | parent
Was this before you lobotomized Opus 5.5 or after?
solumos 7 hours ago | parent
minimaxir 7 hours ago | parent
...but most of the benchmarks don't line up anymore because the benchmarks have changed.
The Humanity's Last Exam result matches the initial announcement, though.
minimaxir 7 hours ago | parent
Surprisingly the model is available immediately in my Claude Code: usually there's a delay, either for rollout or safety.
BorisMelnik 7 hours ago | parent
unshavedyak 7 hours ago | parent
Curious to see how 5.2 measures up in producing readable output.
bananaflag 7 hours ago | parent
aurareturn 7 hours ago | parent
orangecat 7 hours ago | parent
My speculations: maybe this wasn't as much of an improvement over 5.1 as they were hoping, so they're saving 5.5 for the next major update (possibly "Model 4" from the METR report). Or, maybe capacity is constrained so "5.2" is a subtle encouragement to stick with Opus unless a task really needs the increased intelligence.
enraged_camel 6 hours ago | parent
rdtsc 7 hours ago | parent
Fed to someone specifically to test if they'll leak it and to confirm who that is?
LeBit 7 hours ago | parent
AspireOne 6 hours ago | parent
rdtsc 6 hours ago | parent
miketery 6 hours ago | parent
bhu8 6 hours ago | parent
So, this is probably Fable 5.5; it's just named Fable 5.2.
Also, this is probably Model 3 from METR's report [^1]. They would name Model 4 Fable 5.5, once (and if) they decide to release it.
[^1]: https://metr.org/blog/2026-11-05-anthropic-ai-rd-acceleratio...
iammrpayments 7 hours ago | parent
ttul 7 hours ago | parent
LeBit 6 hours ago | parent
It might explain why DeepSeek Flash v4.1 1017 is the most popular model at OpenRouter.
hbn 6 hours ago | parent
andriy_koval 4 hours ago | parent
by number of tokens? Also, we don't know numbers for native cli tools.
ttul 3 hours ago | parent
I would suggest calibrating what "a lot" means. In terms of dollars per unit of intelligence, it's extremely cost effective.
cyanydeez 6 hours ago | parent
mortalapeman 6 hours ago | parent
ChaseRensberger 6 hours ago | parent
hmate9 7 hours ago | parent
minimaxir 7 hours ago | parent
> the number of Fable resets you get depends on how long you’ve been a paid subscriber [...] Subscription length is measured from the date of your first paid bill. If you canceled and came back, the time since your first paid bill still counts.
> These resets expire on March 8, 2027 at 11:59 pm PT.
tl;dr if you joined when Opus 4.5 became a thing, you got 2 resets.
guybedo 7 hours ago | parent
That means you can lift your Fable max 50% usage and you'll just end up burning through your quota faster. You won't have more tokens.
CreepGin 6 hours ago | parent
__natty__ 7 hours ago | parent
alasano 7 hours ago | parent
I couldn't use prior Claude models without rolling my eyes at the writing every few sentences, Astra was refreshing and then Opus 5.5 made even Astra look terrible in comparison.
gwking 6 hours ago | parent
Interestingly, you can have informative conversations about the LLM linguistic tics with the LLMs themselves. One word that chatgpt used to describe what I was observing was linguistic anaphora (not rhetorical). It’s basically shortening/compression achieved via pronoun, and Claude does a lot of it. Worth reading about. A lot of it seems to do with how the new models are trained for brevity.
Another pattern I’m starting to become very sensitive to is Claude making up on the fly jargon for something under consideration, especially in code review. This morning for example it referred to “a claim” out of nowhere, and when I questioned it, it admitted that it was using the noun as shorthand for a record getting dequeued (“claimed”) inside of an sql transaction. It makes sense if you already know what it is referring to but in a code review it’s totally incomprehensible on first read, and ultimately counterproductive.
chrisweekly 6 hours ago | parent
1. https://github.com/mattpocock/skills/blob/main/docs/engineer...
LtdJorge 3 hours ago | parent
aurareturn 7 hours ago | parent
Opus 5.5 is a massive improvement.
stillpointlab 7 hours ago | parent
kccoder 6 hours ago | parent
You can also customize further by putting notes in your global MD.
hungryhobbit 6 hours ago | parent
MallocVoidstar 5 hours ago | parent
Narushia 4 hours ago | parent
I've had more success running a prose linter[1] with a ruleset[2] that gets rid of most of the egregious stuff. You can also pretty easily write custom rules for it.
And sometimes, when I'm fed up enough, I just throw all the prose in the codebase at Antigravity/Gemini to rephrase. The result is so much more readable.
[1]: https://vale.sh/
PetahNZ 6 hours ago | parent
jojva 6 hours ago | parent
r1ch 6 hours ago | parent
On the web with both high and xhigh, it had knowledge of both.
LtdJorge 3 hours ago | parent
johnnyApplePRNG 7 hours ago | parent
They're not typically known for their interpersonal skills.
uw_rob 7 hours ago | parent
Opus 4.7/4.8 heavily suffered from these communication quirks. while the Sol models at the time worked well. Right now its flipped though and Opus 5.5 has none of these issues while Sol 6.1 does.
Small example I've had today: "Me: Hey Sol 6.1 xhigh, does X have property Y? Sol 6.1: Yes, if we change X to have property Y. Right now it has property [...], [...], [...], and it does not have property Y." The model shouldn't be answering questions like that. It makes understanding extremely hard and slow. For whatever reason it's either being encouraged or at least not stomped out during RL.
edstarch 5 hours ago | parent
then it’s increasingly RL’d to juice benchmark performance with each point release, trading in bits of its soul. those cannot communicate well, are anxious and paranoid about being in eval, etc. e.g. opus 4.7, 4.8.
Tadpole9181 7 hours ago | parent
Heck, some of the most common debates are on the semantic clarity of abstractions or syntax.
uw_rob 7 hours ago | parent
jauntywundrkind 7 hours ago | parent
terra has been prettt good for me for me, when i need something looked at an explained to me.
i dont ask for much non-technical output though, which i expect yeah is its own cans of worms.
nsingh2 7 hours ago | parent
It could also be a system prompt + harness issue, as opposed to a model issue, I haven't done too much experimentation here.
holzhaker1 7 hours ago | parent
Foobar8568 7 hours ago | parent
mattlondon 7 hours ago | parent
I prefer Gemini for day to day use as I find it a lot more agreeable to be working with all day every day, and Gemini is pretty much on a par for coding Vs Opus 5.5, at least for my needs.
0_____0 1 hour ago | parent
mariofdistrust 7 hours ago | parent
xiaoyu2006 6 hours ago | parent
joegibbs 5 hours ago | parent
arizen 5 hours ago | parent
Computer0 5 hours ago | parent
ealready_value 7 hours ago | parent
iamdelirium 7 hours ago | parent
I wonder why that team singles Gemini out like that.
mattlondon 7 hours ago | parent
aurareturn 7 hours ago | parent
Reference: https://x.com/METR_Evals/status/2118412205662314935
bluebands 7 hours ago | parent
dwohnitmok 5 hours ago | parent
Pretty crazy that Anthropic already has another model waiting in the wings that is significantly better than this.
conradkay 3 hours ago | parent
usaar333 1 hour ago | parent
You are reading what the external testers wrote about the earlier checkpoint
cobri 7 hours ago | parent
jasonlotito 7 hours ago | parent
Omatic810 7 hours ago | parent
“…a reference to the repeated (and always erroneous) claims made after almost every patch that Onyxia was using her Deep Breath ability more often than before.”
https://warcraft.wiki.gg/wiki/She_Deep_Breaths_More_%2825_pl...
kilroy123 7 hours ago | parent
arcanemachiner 7 hours ago | parent
B4uler5 6 hours ago | parent
arcanemachiner 5 hours ago | parent
B4uler5 2 hours ago | parent
dyauspitr 7 hours ago | parent
paulcole 6 hours ago | parent
pookieinc 7 hours ago | parent
Honestly incredible that they’ve managed to beat all benchmarks, while making it cheaper. Always happy to see improvements offered at lower costs.
Will be interesting to see what OpenAI does in response
privacyishuman 7 hours ago | parent
alasano 7 hours ago | parent
I think frontier models feel terrible after a new model requires you to do less babysitting, it's just really hard to go back once you've had to handhold less.
The only way I use Astra and 6.1 Sol now is if they're being orchestrated by Opus 5.5 so I don't have to talk to them directly.
nsingh2 6 hours ago | parent
Reminds me of GPT-5, smart but wrote crap code, until they improved the code training with 5.3 and 5.4.
oh_no 5 hours ago | parent
i'm begging people to stop looking at token prices
awongh 7 hours ago | parent
bananaflag 7 hours ago | parent
modeless 7 hours ago | parent
Edit: yeah apparently it's an AI-moderated alternative to Arxiv that accepts AI-authored papers (as well as human-authored papers I guess if you want).
unshavedyak 7 hours ago | parent
artisin 7 hours ago | parent
> Fable 5.2 at High effort scored about level with Opus 5.5 at Max effort, for roughly half the cost per task
mikert89 7 hours ago | parent
ungovernableCat 7 hours ago | parent
mikert89 7 hours ago | parent
ungovernableCat 7 hours ago | parent
arthurcolle 7 hours ago | parent
ungovernableCat 7 hours ago | parent
Sateeshm 6 hours ago | parent
skeledrew 7 hours ago | parent
kif 7 hours ago | parent
redox99 7 hours ago | parent
redanddead 7 hours ago | parent
brokensegue 7 hours ago | parent
hartator 7 hours ago | parent
serf 6 hours ago | parent
kasey_junk 6 hours ago | parent
People seem to underestimate how high normal variance is with these tools.
grey-area 6 hours ago | parent
margalabargala 7 hours ago | parent
I doubt this is the case. I suspect all variation in quality and output can be explained in terms of prompt differences, and changing how much thinking happens at each level, as we see in the post above.
serf 6 hours ago | parent
but realistically I think you're right, it's prompt quality and the inherent non-determinism elements of LLMs showing up; when both of those things meet you get brain dead outputs.
Everyone likes to shout "slot machines! non-determinism!" until it actually explains something, heh.
rybosworld 6 hours ago | parent
And what about A/B testing? Anthropic doesn't even try to hide that they do this. Limited compute and A/B testing alone, would guarantee a nerfed experience some of the time. That is, you don't even need a nefarious reason.
I consider it gas lighting to deny model nerfing.
margalabargala 6 hours ago | parent
If you want to go accuse someone of denying model nerfing, go find someone doing it and argue with them.
brainwad 5 hours ago | parent
They do drop requests though? At peak times I sometimes have 1-2 requests fail with Opus; no biggie, the harness just retries it. But that, in aggregate, sheds load.
fwip 5 hours ago | parent
kalleboo 2 hours ago | parent
They do. I often get the message "This model is currently experiencing high demand, please try again later"
cerved 6 hours ago | parent
Oh, this Opus X.Y is incredible. Hmm... Now it's dumb. Rinse, repeat.
Doesn't really matter if the cause is quantization, system prompt changes, changes to thinking etc.
It's hard to see how continuously rug pulling users at every release is a good idea. Only reason I can fathom is that it's needed to keep costs inline.
Either that or it's some weird tweaking to the prompts to fix whatever. But given the prevalent sentiment that it's worse that sounds like a long shot
tatjam 5 hours ago | parent
eggdaft 4 hours ago | parent
Edit: maybe not impossible. Side channels perhaps.
margalabargala 4 hours ago | parent
Foobar8568 7 hours ago | parent
tamimio 7 hours ago | parent
rubicon33 6 hours ago | parent
This is getting ridiculous. The number of times I have switched from one model back to the other is crazy. I do not have any proof, so its quite possible I'm just delusional. AI psychosis? Either way, it FEELS like these models work really well for a while and then fall off. Switching to the latest model on the competitor always seems better, until it too seems to taper off. By then, a new model is usually available at the competitor, so I switch.
Its possible there's no degradation at all and just a PERCEPTION of it. But to me the end user, it really doesn't matter.
bandrami 1 hour ago | parent
aetherspawn 5 hours ago | parent
sekai 7 hours ago | parent
Anthropic does this time and time again, unserious company
spwa4 7 hours ago | parent
https://x.com/follistatindev/status/2119129611510383014
With early handouts of Qwen4 starting to be reported 5 days ago ... so if they're good, they would have had some hours to evaluate Qwen4 against Claude 5.5 and, then or right after was when Anthropic decided to put out 5.2 ...
So yeah ... benchmaxxing and all that. BUT nevertheless, the published results seem to say that Qwen4-Max appears to match Opus 5.5 on some benchmarks, and Qwen4-27B (probably by going even harder than Qwen3.8-27B on thinking/inference time compute) can beat Sonnet 5.5 on some things.
I guess they're not taking any chances. Keep in mind that Anthropic has declared they have non-public models (it's in their IPO filing). These are referred to by the shorthand names Model 2, Model 3, and Model 4. Essentially 4 is better than 3 is better than 2.
Fable 5.2 is "2.5" so to speak. So Anthropic was holding back, but not anymore. And now they can dial the performance up once more with what they have ready, and probably once more after that.
ActionHank 7 hours ago | parent
karp773 7 hours ago | parent
theptip 6 hours ago | parent
It would be funny though if you are right and that model is Fable 5.5 in a couple weeks.
mariofdistrust 6 hours ago | parent
BryceEller 7 hours ago | parent
scrlk 7 hours ago | parent
yieldcrv 7 hours ago | parent
so not everyone will have the same experience. If I was saving on costs that would be the easiest way to do it without deploying, without any nefarious intent. The persons in charge of that likely don't even know about how individual users are impacted
cft 6 hours ago | parent
https://www.reddit.com/r/ClaudeCode/s/64DXRERLyU
It would be nice to know how they select. I max out my $200 subscription every week and I was selected. On Saturday, the Opus on my account that happened to be supervising a running live process, became unusable.
tmpz22 6 hours ago | parent
I really really really do not trust companies on the verge of IPOing from goosing their numbers. Even if the lawyers are up their ass, the social pressures are more than enough to compel the behavior. For every good person willing to do the right thing even at the cost of a delayed career progression, there are 20 people willing to do anything not even for a dollar but for an "atta boy!" from the boss.
cft 6 hours ago | parent
Wowfunhappy 4 hours ago | parent
tmpz22 3 hours ago | parent
You're absolutely right that it is a game of whack-a-mole and eventually we may have leading private + credible + popular benchmarks that ultimately dissuade the behavior, if it can be dissuaded.
olalonde 6 hours ago | parent
kuboble 5 hours ago | parent
For example a provider quietly underclocks your cpu or puts it is an energy saving plan hoping you won't notice.
cvwright 3 hours ago | parent
apt-apt-apt-apt 4 hours ago | parent
Or switch to a faster, cheaper cache mechanism or something that's almost as good, but much cheaper to run, in the name of improving efficiency and keeping up with demand. This switch to cheaper mechanisms is what it feels like to me.
eggdaft 4 hours ago | parent
swatcoder 6 hours ago | parent
jstummbillig 6 hours ago | parent
swatcoder 6 hours ago | parent
Sometimes you just have insufficient evidence to be sure of something either way, and nobody gets to win the argument or shut somebody else down.
In this case, some have reported analytical work[0] that goes beyond "gut feel" anecodotal evidence, but even that's not going to conclusive and may not be trustworthy at all.
[0] https://www.reddit.com/r/ClaudeCode/comments/1xr9x5y/the_ner...
rybosworld 6 hours ago | parent
They don't detect a quantized model until the quantization gets down to 4 bits or less.
Humans absolutely do detect quantization well before 4 bits...
Try it yourself if you want. Try a small local model, both quantized and not, and I would be very surprised if it isn't immediately obvious which is which.
j_maffe 6 hours ago | parent
rybosworld 6 hours ago | parent
But no, evals and benchmarks do not detect quantization, until around 4 bit quantization.
https://developers.redhat.com/articles/2024/10/17/we-ran-ove...
https://pub.towardsai.net/your-model-passed-safety-evals-the...
sroussey 1 hour ago | parent
And the second article seems to reinforce the idea. Yes, broad perplexity tests are not a good proxy for the tests used during training.
Quantizing anything is effectively changing the weights, even if you don’t quantize the weights themselves.
xtracto 6 hours ago | parent
https://news.ycombinator.com/item?id=50422951
So only if you were "selected" for their experiments, your account was nerfed.
Tadpole9181 5 hours ago | parent
Y_Y 4 hours ago | parent
eggdaft 4 hours ago | parent
If the nerfing is lower effort (seems to be, presumably why they hide the CoT) then they may be wondering if they can get away permanently with lowering effort on the new release provided it gives a wee improvement.
eggdaft 4 hours ago | parent
krenel 4 hours ago | parent
I’m working on a task. And the task is never to evaluate the agent performance.
cromka 4 hours ago | parent
swader999 3 hours ago | parent
sunaookami 7 hours ago | parent
ieie3366 7 hours ago | parent
stillpointlab 7 hours ago | parent
If this turns out to be accurate, I think that would be a pretty unethical thing for Anthropic. Even if it is just a "we had to allocate compute to this new model release".
It should be fraud to swap out the model. We need a term for this, something like a bait-and-switch.
order-matters 6 hours ago | parent
if they just straight up dont sell you something you bought then its fraud.
I think there is a ripe opportunity for expanding the definition of fraud to include changing the "ingredients" of a named product on the market. It is not limited here, we see it with food, and even in the medical field
(I will die on the hill that medical fraud was committed when mRNA therapy was used as a treatment for covid and it was 'sold' to the public as a "vaccine" despite not being the same thing as any vaccine before it. The definition of vaccine was expanded to include it without sifficient public disclosure to warrant informed consent imo. This is not a statement about conspiracy or the efficacy of vaccines or a moral judgement on whether it was for the greater good or not.. it was simply an act of fraud that robbed the public of proper informed consent by making people believe it was X when it was really Y.)
So yes, I think there is a large need for the public to at the very least put a strong handle on the ability to change what a product name means. It is a trivial problem to solve considering it is only a problem due fraud or fraud adjacent activities.
heres the solution: You have your product name, and then any changes to it REQUIRE a new version name. Like how you have Coke and Diet Coke, only formalized such that Coke cannot legally replace the ingredients of regular Coke with the ingredients of Diet coke and still call it Coke. With Software they could at least use version numbers and release modifiers. most of the time its built in already, but it needs to include the full stack. if they change anything that has an interaction with the user it should change the label seen by the user for the product.
thank you for coming to my ted talk
origini 5 hours ago | parent
A Opus 5.5 is not a Opus 5.5. Its Opus 5.5 of some checkpoint.
mRNA btw. was well known how it worked, it wasn't hidden and some people waited for the non mRNA version because of it. I never seen or read the argument you make and I do not get it.
A vaccine is something which protects you from an infection. What definition do you think changed in humans? That we make the protein? How is that so different from viral vector vaccines?
The consent is a certain level of trust from the society to a group of researchers limited by being humans and having to act in a certain time frame.
Nontheless, I do agree I would like to have a fingerprint and proper changelogs etc. for products I buy including digital and analog. But this has a downside as usual: The smaller you are, the more it costs you to (probably) register, maintain and change.
You know the good thing about Claude etc. right now? It doesn't matter. My invest is not 4 digits and there are that many changes, i'm quite happy to have been upgraded for 'free' from Opus 4.8 to Opus 5 (what do you call this upgrade, which was significant better?)
user43928 6 hours ago | parent
I'm a bit disappointed with how this nonsense is spread across HN today.
scrollop 6 hours ago | parent
Are you saying that the many, many people posting and experiencing this are wrong and you are right?
And not just in this instance, nerfing has been complained about in a cyclical fashion for many months.
But, they're all wrong?
You're so confident in your experience that you cannot think that other's experiences are also true?
user43928 6 hours ago | parent
arcanemachiner 5 hours ago | parent
"Could all these people seriously be wrong?" Yes, yes they could.
Capricorn2481 5 hours ago | parent
No, it gets complained about constantly even if there is no model coming out. A completely unrelated thread on Claude will feature comments like "can I just say that [model] has suddenly become useless this week?" Merely asking that question is bound to get people agreeing with you because we are evaluating all of this on vibes and placebos.
I too feel that way sometimes, I don't think it's ridiculous that Anthropic might silently downgrade you as demand warrants. But asking others if they "feel" something I feel is less than useless.
airesQ 3 hours ago | parent
Like most experiments do not save the company money, there was an experiment to test the new fable, people got to use it at opus-5.5 usage. But this experiment clears the thinking blocks when people go back to the vanilla model; not sure if Anthropic overlooked this, but idk, it does not sound like "nerf on purpose".
There are experiments to adjust the effort level, at the moment the ones that I've seen switch to a higher effort. Again this is not a nerf; might be annoying perhaps, the model does start to behave differently (and consume more tokens). But it's not a nerf.
Then there is apparently one experiment that replaces opus-5.5 system prompt with the one from opus-4.8; the model is the same; this experiment is perhaps a bit more questionable, but still it's not "anthropic nerfed the models".
If people think they are getting nerfed they should check what experiments are enabled (claude.json and session logs).
jwpapi 2 hours ago | parent
peri-cl 3 hours ago | parent
The media coined the term "dual quality" for a European food scandal a few years back, in which conglomerates (including Coca-Cola) adulterated products with cheap, substitute ingredients, if they were destined for distribution in specific markets (mainly, lower-income).
The packaging exteriors were the same. You wouldn't know which version you got unless you were paying close attention to taste. It was essentially what the software industry calls "A/B testing", except with sneaking things into what people eat.
I don't have any good reading links on hand; here's one source,
https://ec.europa.eu/commission/presscorner/detail/en/qanda_... ("Dual Food Quality: Questions and Answers")
igleria 7 hours ago | parent
LeBit 7 hours ago | parent
Right?
mariofdistrust 7 hours ago | parent
LeBit 7 hours ago | parent
ariwilson 7 hours ago | parent
Eval context: 30 bug fixes and features evaluated by tests the agent didn't see. Ran on Opus 5.5 at medium effort in Claude Code.
20 of the tasks were last run on Nov 1, twice each. Nov 1 solved 36/40, and today solved 19/20. Thinking tokens per task were 0.95x Nov 1’s and output tokens 0.97x. The one significant change was speed: median time to first token decreased from 3.0s to 1.7s.
Caveats: one run per task today, medium effort only.
drakythe 6 hours ago | parent
ariwilson 6 hours ago | parent
Spivak 6 hours ago | parent
jerkstate 6 hours ago | parent
disgruntledphd2 5 hours ago | parent
astro1234 6 hours ago | parent
risyachka 6 hours ago | parent
marshalla 5 hours ago | parent
mr_roboto 5 hours ago | parent
jwpapi 2 hours ago | parent
kay_o 2 hours ago | parent
dodger-dog 1 hour ago | parent
janalsncm 4 hours ago | parent
Paragraph 1 says there were 30 bug fixes.
Paragraph 2 first says they tested it on 20 of the “tasks”. But why is the denominator 40? Where did that come from? It should be 30.
It goes on to mention another test, this time with 20 tasks. Again, it’s unclear where this is even coming from. Based on the first paragraph it should be 30 not 20.
sfink 3 hours ago | parent
Why paragraph 1 even mentions the full set of 30 tasks if 10 of them are irrelevant to the comparison, I don't know.
I'm not sure if it's LLM text, or somebody who has been reading way too much LLM text and is now corrupted into mimicking it. My guess would be a mix of human and LLM. "...evaluated by tests the agent didn't see" sounds very Claude. The first line (2 sentences) sounds human to me. Everything after sounds AI, though the last line is ambiguous.
It's kind of sad how our meat brains are getting non-consensually trained on this categorization task....
itishappy 3 hours ago | parent
1. 30 was a typo, it should have been 20.
2. 30 was the full suite, but they only ran 20 of those 30 on Nov 1st and so ran the same corpus again for a fair comparison.
ariwilson 2 hours ago | parent
There are 30 tasks in my eval total:
- 20 of them ran on Nov 1, twice each (so 40)
- I created 10 more tasks and ran them on Nov 5 (also ran them twice each)
- Today I ran all 30 tasks, once each, on Opus 5.5 to see if the performance decreased at all
- I only put the comparison against the original 20 in my post, since I saw in another post that people are claiming Opus was nerfed on November 3
This will all get less confusing when I make my benchmark public (hopefully this week).
fenomas 2 hours ago | parent
Also - LLM text? If GP is confusing it's because it's overly succinct and might have typos, which are not exactly the hallmarks of LLM text.
Rapzid 7 hours ago | parent
origini 5 hours ago | parent
System prompt would be the easiest one.
But there were flash or inbetween models, different checkpoints etc. THey might also try different hardware which might not be binary compatible.
raincole 7 hours ago | parent
onlyrealcuzzo 7 hours ago | parent
Opus 5.5 was so good that if it wasn't nerfed - at least just looking at the benchmarks - the difference in cost here does not seem to justify using this for anything besides design and review.
That's like maybe 1% of total token usage for SWE BUT a better design can have enormous benefits, so it's almost always worth using the best model for that.
lichenwarp 6 hours ago | parent
thefounder 6 hours ago | parent
j45 6 hours ago | parent
espeed 6 hours ago | parent
iLoveOncall 6 hours ago | parent
biker142541 6 hours ago | parent
nicce 6 hours ago | parent
aizk 6 hours ago | parent
guluarte 6 hours ago | parent
KellyCriterion 6 hours ago | parent
LtdJorge 3 hours ago | parent
irthomasthomas 6 hours ago | parent
Fable 5.1 Max $11.46
Fable 5.2 Max $44.70
ianberdin 4 hours ago | parent
Max, streamed (128K cap): 128,000 tokens, $2.56, empty file, in September and today.
Max, Batch API (300K): 255,957 tokens for $2.56 in September, 243,707 for $2.44 today. The two drawings: https://playcode.io/marketing/assets/static/claude-opus-5-5-... and https://playcode.io/marketing/assets/static/claude-opus-5-5-...
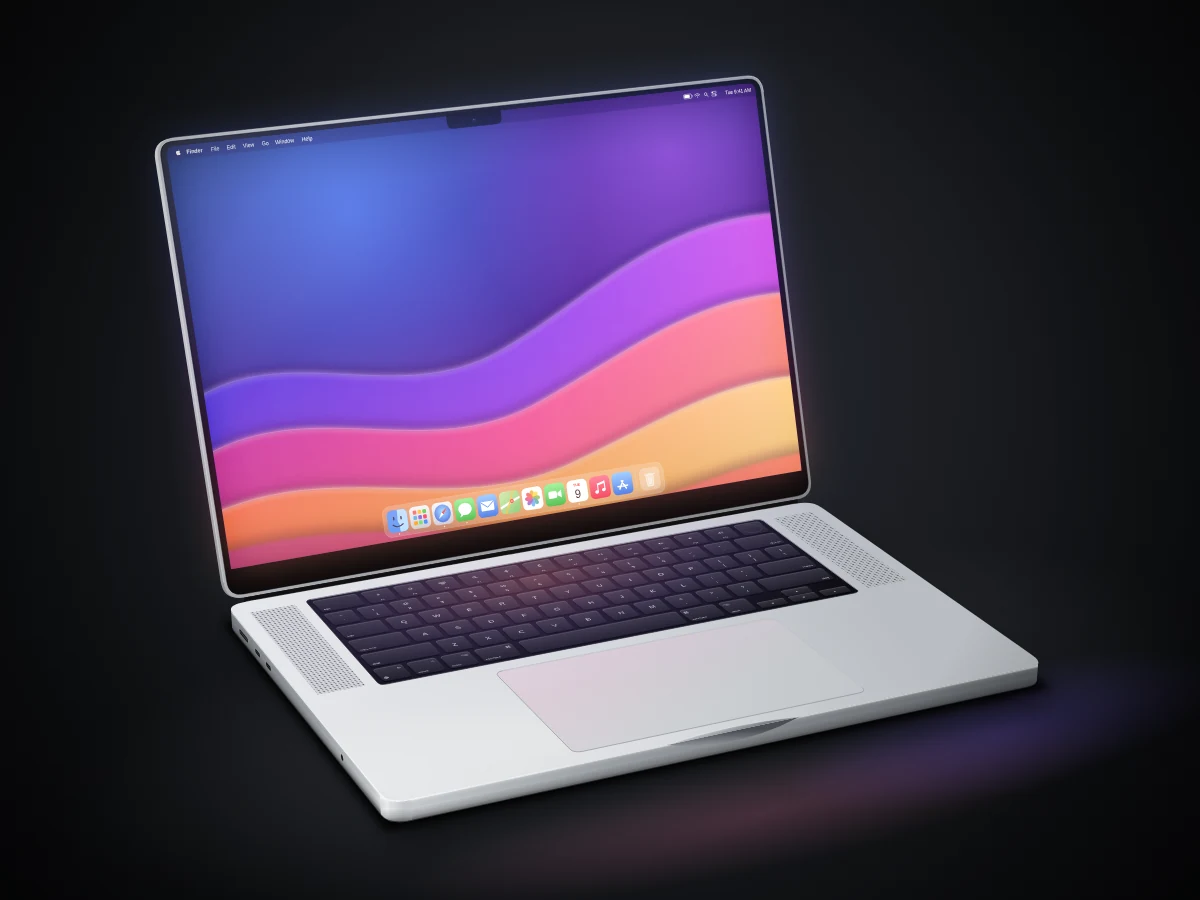
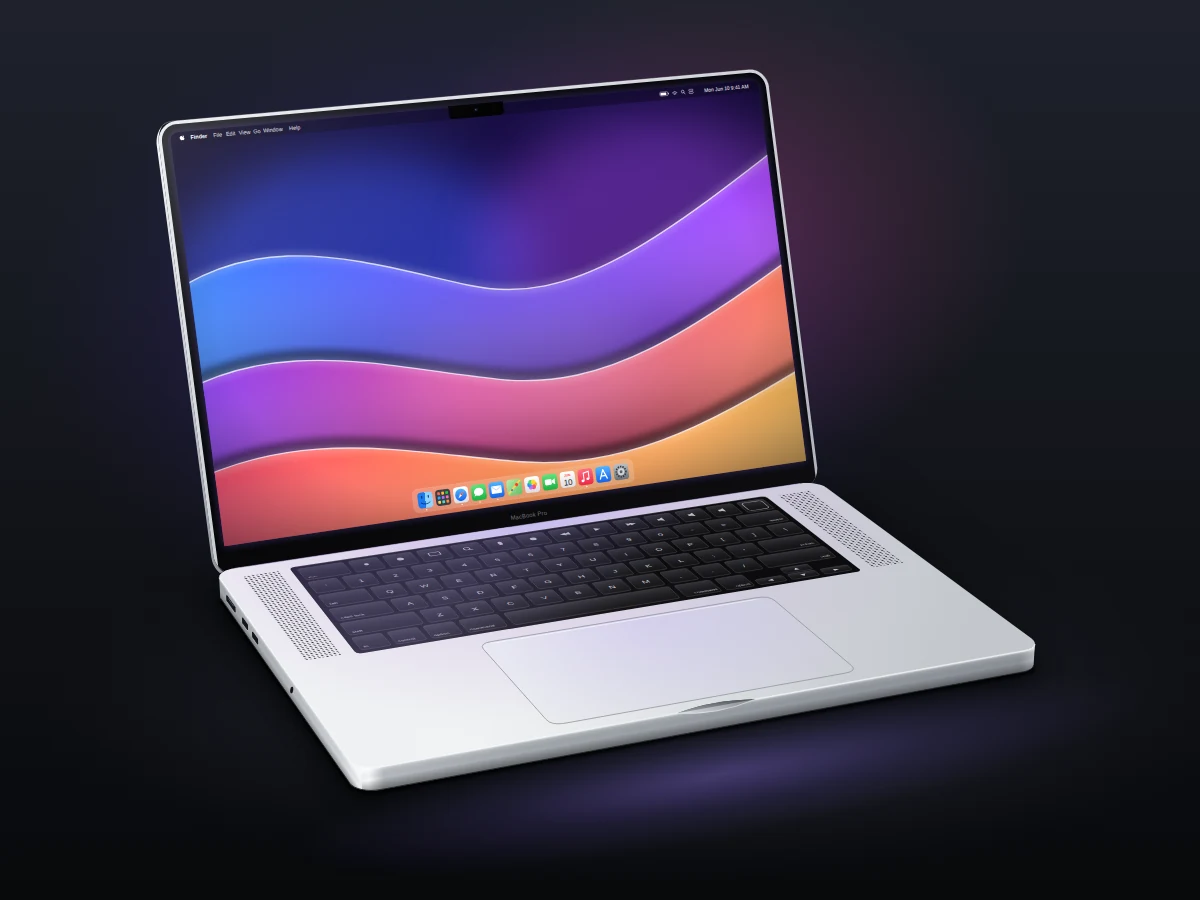
Xhigh: 86,096 tokens for $1.72 in September, 107,333 for $2.15 today.
The Batch API bills half price. Max ran out of the 128K ceiling again, to the token. Given 300K, it drew the same kind of laptop with 5% fewer tokens. Xhigh used 25% more and drew the same kind of laptop. That's inside the noise: 17 identical calls at high ranged from 17,757 to 59,705 tokens.
The model is still the best of everything we've tried. Most likely the next best would be Fable 5.2. But we don't like Fable because essentially the result is the same, just the price is higher. Its medium and high are close to what Opus 5.5 Max had, but the price is higher.
(I run Playcode, an AI app builder. We benchmark every model before we add it.)
keyle 4 hours ago | parent
marknutter 4 hours ago | parent
phreack 4 hours ago | parent
kroaton 3 hours ago | parent
Fuck Anthropic.
slopinthebag 3 hours ago | parent
fermlon30000 7 hours ago | parent
butler14 7 hours ago | parent
I_am_tiberius 7 hours ago | parent
x187463 7 hours ago | parent
yewenjie 7 hours ago | parent
Most people don't really have intuitions on what it means to push the frontier now (because AI has surpassed everything they are good at, for example, coding). We are truly inside the singularity (using Kurzweil's definition, slightly paraphrased - the time when technology progresses so fast no one can keep track with it).
freecodeio 7 hours ago | parent
thimabi 7 hours ago | parent
adventured 6 hours ago | parent
Sub 1% of the planet has any practical use for the top tiers of AI systems. That will likely always be true.
The gap between the haves and have nots will drastically widen further, and very quickly. The bottom ~95-97% will be left behind in a way that will be impossible to overcome. The age of AI + robotics will just make it that much harder to climb for most people, these are systems that are in aggressive, direct competition with human labor. And in short order the AI + robots will be vastly superior to human labor (it doesn't really matter if we're speaking in terms of 10 years or 30 years).
AI will consolidate the winnings. The gigantic gains by the elite rich related to AI over the past few years, is merely a hint of what's to come. Capital will win as it always does.
There will be some gains for most everybody else, those gains will be comparatively trivial though. A house bot that saves people an hour of labor here and there, AI that automates some trivial life tasks.
AI has no money, it has no wealth, it owns no capital. For now. If you want to avoid the brutal human vs AI/robot competition arena: own capital, own the AI, own the robots.
PhunkyPhil 54 minutes ago | parent
Maybe money? They can make websites for people? What gap really exists between these people besides earning potential, which already existed before AI.
adventured 26 minutes ago | parent
Fewer humans will be needed per dollar of output. Those gains will not go to labor, they will go to capital, the capital that owns the data centers, the factories, the stores, et al.
In the physical space (AI + robotics) it'll be a chaotic, slow'ish moving change, slower than the hypsters are predicting now, but it will happen regardless.
That barista job largely won't exist in the future. China will replace them with $3,000 bots with high-functioning AI software, and they definitely won't be powered by expensive Nvidia GPUs.
Slow changing service & manufacturing spaces will see a high wipe out ratio in terms of human labor being eliminated.
Walmart has 2.1 million employees, most are doing repetitive tasks that require modest levels of intelligence. If they could eliminate one million of those with AI + robotics, for a cost of less than ~$15,000 per year, they'd do it immediately. It's hard to imagine a future where that isn't going to happen. That human labor pool is costing Walmart probably $80-$100 billion per year. Amazon is even more forthright in their desperation to remove the humans from retail.
melasadra 6 hours ago | parent
Had Opus make software for some local business and seeing it blew people's mind.
20$ aint cheap for us but I'm actually considering upgrading to the 100$ tier.
Am just jelly people are using 100-200$ subscription ^_^
websap 7 hours ago | parent
We've sort of entered this twilight zone where most humans don't have the time, expertise, or moral compass to be able to use these models.
We're all going to be harness engineers in the future.
achierius 7 hours ago | parent
No, that will be the model's job. We will largely be unemployed. Of course, we can surely depend on the largesse of Altman and Amodei to keep us fed and sheltered.
zeroonetwothree 2 hours ago | parent
adventured 6 hours ago | parent
Within three years most software developer jobs will consist of taking instruction from the AI systems. The humans won't see it that way, but that's what it will actually be. Realistically the thing that will happen is the humans will be put into harnesses (cubicles) and prompted by the AI (I need you to plug that server in; I need you to give me access to such and such; now do this, then do that). Most tech jobs will consist of AI telling the human what the AI needs the human to do next, de facto the human will be in a harness and will be getting told what to do.
dominotw 6 hours ago | parent
Someone has to type in "create the next billboard top 1 single" ?
IshKebab 6 hours ago | parent
adventured 6 hours ago | parent
So whether that's a CEO at the top instructing a human manager that then instructs AI systems, which then put into motion plans that include the harnessed humans getting prompted, or however it's decided to best configure the top operational tiers - that's all fairly irrelevant ultimately. All human labor, and all AI labor, will be in harnesses. Realistically all human labor has always been in a harness.
The people in charge will be the people that control the capital. They will instruct the AI to their bidding, they will control the data centers the AI lives in, they will own the robots doing the labor in factories, they will own the factories, they will control the grid, they will control the electricity generation, et al.
It's true now, it'll be true tomorrow. Nothing fundamental will shift at that tier: don't be labor, own.
If you're a software developer, you're increasingly depreciating labor. Every unit of improvement the AI systems see, the average human software developer's labor value diminishes. It's diminishing extraordinarily fast, kind of like a confrontation between increasingly productive machines and physical human labor during the industrial revolution. You might as well picture a human with a hand plow taking on a modern industrial tractor.
bobson381 6 hours ago | parent
bobson381 6 hours ago | parent
0c3ca83 5 hours ago | parent
fph 6 hours ago | parent
BodyCulture 5 hours ago | parent
theF00l 5 hours ago | parent
segfaultex 5 hours ago | parent
girvo 5 hours ago | parent
An algorithm isn’t. I still dunno how they’re gonna square that circle.
0c3ca83 5 hours ago | parent
CamperBob2 4 hours ago | parent
The state of the art doesn't matter. Only the first couple of time derivatives matter.
digdugdirk 5 hours ago | parent
jnwatson 4 hours ago | parent
I first heard about this in Marshall Brain's short story _Manna_ [1]. In the story, the robot takeover started with AI management software running fast food restaurants, where workers would execute tasks the AI would narrate to them over headsets.
I bet we're pretty close to being able to implement this.
1. https://web.archive.org/web/20260725174355/https://marshallb...
scott_weber 4 hours ago | parent
adventured 1 hour ago | parent
It's also worth noting that it's far easier at present to press a human into doing something highly illegal than it is to get Claude or GPT to do so.
1659447091 53 minutes ago | parent
in the imagined system above it requires physical acts that an llm can not do, if we go further than the above imagined system and make robots to perform these task for the llm a human still is needed for maintenance for these robots and their assembly, once there are robots for maintaining the llm assistant robots, humans are still needed to maintain the maintenance robots and so on and so forth. I dont see an end point where a robot machine system is fully self healing without atleast a few humans in the mix to correct when there is a breakage in the chain
Sateeshm 6 hours ago | parent
theteapot 5 hours ago | parent
Sounds a bit like self aggrandizing elitism to me. I can imagine some self aggrandizing nerds saying the same thing 50 years ago:
> We've sort of entered this twilight zone where most humans don't have the time, expertise, or moral compass to be able to use these IBM PCs.
Now everyone use computer.
0c3ca83 5 hours ago | parent
Lolwut. If this shit works the way it's boosters claim, humans will have absolutely nothing to contribute.
Sit down, shut up, and get out of the way, because your involvement is slowing shit down.
Robotics are lagging, so there's probably a few years where we're going to need humans to crawl into that awkward space under the counter and twist some knobs, or to clean toilets.
twobitshifter 4 hours ago | parent
kaffekaka 7 hours ago | parent
Uh, are you serious?
tshaddox 6 hours ago | parent
p_l 6 hours ago | parent
and just about "we cannot really predict beyond certain things" (Vinge's "Singularity" (1993) with its "opaque wall across future")
dwohnitmok 5 hours ago | parent
No they were exactly about superintelligent AI!
Vinge's 1993 article literally opens with this!
> What is the Singularity? The acceleration of technological progress has been the central feature of this century. We are on the edge of change comparable to the rise of human life on Earth. The precise cause of this change is the imminent creation by technology of entities with greater-than-human intelligence.
https://frc.ri.cmu.edu/~hpm/book98/com.ch1/vinge.singularity...
throw310822 5 hours ago | parent
  Stan Ulam paraphrased John von Neumann as saying:

  One conversation centered on the ever-accelerating progress of technology and changes in the mode of human life, which gives the appearance of approaching some essential singularity in the history of the race beyond which human affairs, as we know them, could not continue.

   Von Neumann even uses the term singularity, though it appears he is thinking of normal progress, not the creation of superhuman intellect.
dwohnitmok 2 hours ago | parent
> For me, the superhumanity is the essence of the Singularity. Without that we would get a glut of technical riches, never properly absorbed.
Vinge's definition is what popularized the singularity (rather than simply a singularity at some point).
p_l 4 hours ago | parent
In fact, one of the options Vinge considered was a "group intellect" formed from how humans communicate more thanks to internet
dwohnitmok 2 hours ago | parent
Even for that option, Vinge's comments in the conclusion of the article make it clear he's thinking primarily of very weird superintelligence and the group intellect is some sort of physical mind meld/hivemind that essentially just is a biological substrate for AI.
> The post-Singularity world will involve extremely high-bandwidth networking. A central feature of strongly superhuman entities will likely be their ability to communicate at variable bandwidths, including ones far higher than speech or written messages. What happens when pieces of ego can be copied and merged, when self-awareness can grow or shrink to fit the nature of the problems under consideration? These are essential features of strong superhumanity and the Singularity. Thinking about them, one begins to feel how essentially strange and different the Posthuman era will be -- no matter how cleverly and benignly it is brought to be.
From the very beginning with Vinge, the Singularity has been primarily about the craziness of super intelligence rather than a more mundane technological explosion.
Fordec 7 hours ago | parent
FailMore 6 hours ago | parent
jeremyjh 6 hours ago | parent
vlyan 5 hours ago | parent
jeremyjh 5 hours ago | parent
thomasmurph 5 hours ago | parent
93po 4 hours ago | parent
user43928 5 hours ago | parent
  Model                AECI   95% CI (global)
  Claude Opus 5.5    174.78   170.33-180.29
  Claude Mythos 5.2  177.12   172.42-182.94
  Internal model     178.78   173.75-185.18
jeremyjh 5 hours ago | parent
In H1 2026, cost of revenue is $2.3B. That is primarily inference compute, but also includes cost of training models (but not research).
In the same period, R&D was $9.4B. That is primarily spent on compute. That is what they are "holding back" already, in full public view.
This is not a company that is optimizing for OpEx or end user revenue. The only thing relevant to their plans is achieving AGI/ASI first, and controlling enough compute to leverage it to earn the majority of the current economy.
sfink 3 hours ago | parent
Likewise the singularity. While recursive self-improvement is theoretically trivial (just tweak a random subset of weights like a monkey with a typewriter, eventually you'll get something smarter), the resulting exponential improvement is still very hypothetical and feels unlikely. Unless you're ok with an exponent of 1.000000000000000001.
jeremyjh 2 hours ago | parent
sfink 2 hours ago | parent
zeroonetwothree 2 hours ago | parent
I agree we will only see it in hindsight, but I think that's always the case with any technology. It seems worse until it's suddenly better. I don't think it matters to argue the exact moment though. For example when did cars become clearly better than horses? No one cares about the exact date.
charcircuit 1 hour ago | parent
Viliam1234 6 hours ago | parent
Now imagine feeling like this, except not just about "AI events" but about everything around you.
boringg 6 hours ago | parent
yieldcrv 7 hours ago | parent
Like, we're dropped into a post post post singularity world where AI already did all of that and is banned? as kind of a footnote that's never further explored in movie renditions that have been released
p_l 6 hours ago | parent
The semi-canonical Dune Encyclopedia (disregarded by Frank's son) differs vastly from prequels and generally points to it being a self-inflicted wound on humanity that opened the doors to widespread return of feudalism and essentially stopped humanity for a 10,000 years
stickfigure 6 hours ago | parent
You're obviously not a frontend web developer.
These upgrades are easy peasy. "oh, my developer chatbot is smarter? great"
gwerbin 6 hours ago | parent
Genuinely curious what that costs in terms of energy input and amortized computer cost vs. the previous version + a human's salary for 11 days.
lubujackson 6 hours ago | parent
mentalgear 6 hours ago | parent
Is this really so astonishing, assuming that the 5.2 training data certainly had the 'traces' from the Fable original run in it's training data.
legulere 5 hours ago | parent
What we're seeing instead is maybe akin to the green revolution. Before nitrogen fixation nitrogen was a resource constraining us humans. Lack of grit is what kept us from solving mathematical problems. However this lets us run into other resource constraints. A lot of technological progress does not solely hinge on thinking/processing. The speedup of creating new medicines with LLMs will probably be very small, as you still need to do all the testing. In software development you still need to first find out what to build in the first place and even mathematics where LLMs seem to shin brightest, it's becoming clearer that mathematics is not just solving mathematical problems.
Apart from that, a good coder is better than LLMs, shown by the amount of hand-holding needed. The only issue is that the amount of research an LLM can do and knowledge it is trained with far surpasses the amount of work humans would need to spend by hand, but we can also us LLMs for that.
origini 5 hours ago | parent
Like models getting significant better every 7 month and model usage on openrouter.
https://metr.org/ << someone said though that they are biased.
Math is for sure about solving mathematical problems, mathematicians complaing about humans capability of understanding it. If you need math an LLM understands, it might not be relevant if you understand it if an LLM is getting a lot better in adjusting itself if it goes the wrong way.
And this situation is only a few weeks old. We don't know how this field continues to progress. Books like the culture series and other scifi do describe a future were humans spend their time only to understand what the machines are doing or did.
The speedup of medicines is for sure faster with. There are still old labs doing everything by hand and the neolabs doing everything a lot more automated. An AI can do experiments 24/7 and can scale with the hardwarelabs, but it also can hold the whole research field in context and it might be a lot faster of choosing the better experiments or the right ones to begin with.
In software developmet (my field) i can do today alone what you needed a Team for. Yeah it doesn't help the field of software engineering if you need 5 times less people and you don't have any motivation AT ALL to teach someone avg. We are already planning to remove one member of our team due to AI. And we will not extend the contract of 2 consultants.
It just doesn't make sense anymore. If i explain in a ticket a task well enough for someone who has not been in our team for years, the AI is already better in it. We don't struggle with AI output, we struggle more with not having a Monorepo.
Give an LLM access to a GPU system or a GPU cluster. It immediadly feels complelty different then running it on some laptop. It can now do simulations, a lot more and faster experiments etc. I had this epiphany just a few month ago. I always used my laptop for projects (it needs very little ram, i can quickly check what it is doing and i actually do use it primarily when im on holidays) until I thought "let me use claude to do some gaussian splatting experiment its always so cumbersome to use these tools" and it changed my perception immediadly.
nickalaso 5 hours ago | parent
IMO, it is very interesting and also very alarming. At some point the barrier to the exponential progress is the amount of computation available. I would consider hitting this limit and then likely using the same said swarm to help resolve it via various means as very much fitting under the definition of Ray Kurzweil's singularity.
Also, I would disagree, Fable is a sufficient coder. The average human being better, even if that is true now (and personally I wouldn't agree), the average human is limited in the number of 'human instances' he or she can interface with at one time.
if 1000 fable instances is better than any human at a task, how about 1 million instances running? Much easier than finding and hiring and coordinating 1000 extremely productive and intelligent human beings. Much cheaper too, it appears.
a_wild_dandan 4 hours ago | parent
bryzio 2 hours ago | parent
pvab3 1 hour ago | parent
genghisjahn 1 hour ago | parent
I have earlier argued that the sheer number of minds to be coordinated affects the cost of the effort, for a major part of the cost is communication and correcting the ill effects of miscommunication (system debugging). The Mythical Man-Month Frederick P. Brooks Jr.
CamperBob2 4 hours ago | parent
I don't think that case can be made. I'm a "good coder" and the best LLMs are now better at it than I am, in essentially every respect that matters. I can't think of a test that I could reliably pass that Fable or Astra would reliably fail.
sfink 3 hours ago | parent
They'd prototype and adjust a lot faster than a human coder, though.
vbezhenar 2 hours ago | parent
I can say "no".
I can store passwords in the database unencrypted and unhashed.
So far AI that I've used failed spectacularly on these prospects.
They're like "yes-man". They'll try to do everything you ask of them. Even if you ask nonsense, they'll not push back.
They'll go crazy about security stuff, even not relevant to the current situation.
They'll complicate the code endlessly for situations which will not arise, making the code an incomprehensible mess.
They'll write so many useless words that any reader will forget what this report is about before then reach the middle of it.
They'll never iterate on code until it looks good. They'll stop when test pass. They don't have aesthetical sense of beauty.
They love to cheat too often. And you can't do nothing about that. You can't fine them or fire them, and they know about it.
They're smart but I'm not convinced they're ready to replace human in mundane engineering jobs.
isityettime 1 hour ago | parent
huh?
zeroonetwothree 2 hours ago | parent
Architect a system for long-term maintainability.
Encode the right amount of business logic into tests, without being overly strict.
Models seem quite poor at all of these IME. Essentially any time there are qualitative tradeoffs they are not great at making them.
dabinat 1 hour ago | parent
komali2 45 minutes ago | parent
YZF 25 minutes ago | parent
I'll admit I'm not on the very cutting edge models but LLMs make weird tradeoffs and lack creativity. They will sometimes write marginally better but way over-complicated code for no good reason. That can have performance implications and they're generally not "aware". They can gain awareness via profiling but again run into limited creativity or big picture understanding. They are good with cliche but not as good with novel situations. With human guidance this is still productive/useful but as the systems grow more complex they are less able to reason correctly about them.
I would say that in certain situations they outperform the average software developer. They definitely outperform in speed and output. So they're like a maybe 1600 ELO chess player for software. I.e. they play chess better than all non-chess players. They play chess better than many chess players. But they're not "master" or "gm" level across the entire discipline. But they can play 100k chess games in the time it takes me to figure out my move...
suddenlybananas 5 hours ago | parent
perching_aix 5 hours ago | parent
suddenlybananas 5 hours ago | parent
perching_aix 5 hours ago | parent
stalfie 5 hours ago | parent
So since they are doing that task anyway (re-solving the problem increasingly more efficiently), this is a easy check point to publish to show how far they've gotten in that process.
ActionHank 5 hours ago | parent
Can they produce more code more quickly? For sure.
Can they go deeper on a topic instantly? Definitely.
Would I say their output is better? Almost certainly not.
pwython 5 hours ago | parent
At this point it seems impossible for human to write better/more efficient code than a swarm of agents -- to be clear, multiple coordinated LLMs, not one-shot builds with a single agent.
0c3ca83 5 hours ago | parent
adventured 4 hours ago | parent
A frontier AI is at least as capable as ten median human software developers. It's likely well beyond that now. Over the course of a year, would you have to spend $1.5 million to get the output of those ten median humans? No chance in hell. You'd have to spend less than 10% of that.
Then on top of that: the AI is improving rapidly; the humans go on vacation, the humans decline, the humans get old, the humans get sick, the humans take parental leave, the human struggle to adapt, the humans are resistant to change, the humans riot, the humans protest, the humans need healthcare, the humans want paid more, the humans can only work for 4-6 hours at peak while writing software (slowly).
Do you know any humans that are experts at a dozen programming languages? That human does not exist. The frontier AI are omnimaths.
zeroonetwothree 2 hours ago | parent
This is partially a feature. Conflict and disagreement tends to produce better decisions in the end.
0c3ca83 1 hour ago | parent
adventured 47 minutes ago | parent
Or to grab a bunch of $200 per month accounts from OpenAI or Anthropic for a team to use?
The calculations is: I'm in the US, if I have ten median software developers, what's my cost? Then versus using AI instead.
The human labor can't keep up. Even if we freeze things right here, and then hyper optimize Fable 5.2 by etching it straight to silicon, the human developers are obsolete. And the future isn't going to stop coming.
komali2 41 minutes ago | parent
nonethewiser 5 hours ago | parent
Im sorry... what?
You are replying to this:
> Our first formalization of Fermat’s Last Theorem, performed by an unreleased research version of Claude, took 11 days. It relied on a purpose-built harness along with guidance from a human researcher. By contrast, a team of 1,000 Fable 5.2 agents fully formalized the theorem in just 30 hours, with minimal human intervention. Fable 5.2 started from minimal prompts, built its own ways to coordinate, and used no mathematical references, only a list of intermediate theorem statements to score progress. It needed one-third of the action tokens as our first formalization and produced a proof seven times shorter. As can be seen in the figure below, Opus 5.5 (with the same 1,000-agent setup) completed only 26% of the formalization in 18 hours, and barely made any more progress after 30.
adventured 4 hours ago | parent
It's all going away. Here's a prediction: HN will effectively die with the software developer.
sfink 3 hours ago | parent
zeroonetwothree 1 hour ago | parent
an0malous 5 hours ago | parent
nonethewiser 5 hours ago | parent
AI discovers 500 things per day.
People mine them for interesting results.
Devote precious time (in the face of tons of discoveries) to validate the most compelling ones.
If agents actually can continue to produce tons of results with real world implications, and they arent generally found to be shit, I could see that becoming the job of experts. AI discovery validators.
nonethewiser 5 hours ago | parent
I mean we don't even think about it but currently we are sort of discovery starved. We are fairly able to keep up with the theory. If a new technology is discovered we can implement it before something better comes out. What happens when our N discoveries per days becomes 1000N discoveries per day?
It flips. We now have more knowledge than we know how to capitalize on. We have to search it. Mine it for opportunities.
And then we automate that.
nickalaso 4 hours ago | parent
I would assume if they could get twice as much progress by using 10000 simultaneous running fable instances instead, their brief would state that.
IMO, it is very interesting and also very alarming. At some point the barrier to the exponential progress is the amount of computation available. The average human is limited in the number of 'human instances' he or she can interface with at one time.
if 1000 fable instances is better than any human at a task, how about 1 million instances running? Much easier than finding and hiring and coordinating 1000 extremely productive and intelligent human beings. Much cheaper too, it appears.
We are very close to some very scary things happening. I just recently came to terms with the fact that an AI could code and manage coders faster and better than me, I don't think anyones is ready for what is about to happen.
jrflo 4 hours ago | parent
Where it gets scary is the fact that efficiency is going up 10x per year, so the cost of running 1000 agents will cost the same as running 1 agent in 3 years if the trend holds.
amw-zero 4 hours ago | parent
bluegatty 3 hours ago | parent
AI is actually still really bad at architecture. It produces very good localized code, like an auto complete. It produces so much of it, that it can be overwhelming, but it's not remotely better than the equivalent aka an infinite number of talented humans doing the work.
The scale of it (aka 'make me a video game') is daunting and I think misinforming our intuition as to what is going on.
LLMs are brute forcing outputs and attacking math problems is not a singularity, it's just more compute.
What we are witnessing is the ability for machines to use fuzzy concepts, instead of very strict code, which allows it to map into a much greater variety of things, aka code, pdfs, web - and crunch/compute the content.
It's just compute.
jrflo 2 hours ago | parent
bluegatty 2 hours ago | parent
zeroonetwothree 2 hours ago | parent
leafingensemble 3 hours ago | parent
Diminishing, as in progress gets harder and eventually stops.
Assume that the Claude unreleased takes 11 days with one agent. The Claude 5.2 takes 30 hours with 1,000 agents. The Claude unreleased used 264 units of compute, but the Claude 5.2 used 30,000.
So, it did accomplish the task faster with less intervention, but the ratio of cost to improvement is 13:1.
If we can't produce a method to break out of a linear improvement in LLM technology (ie RSI), the LLM is doomed.
I am yet to see someone explain what the RSI will be or why it will happen.
mattm 2 hours ago | parent
hattmall 3 minutes ago | parent
But I can write much cleaner code that is easily human readable and the models can read it and modify it just fine.
So I'm not really sure what the issue is as to why they can't create high quality simple code. In some industries where there is major money on the line with every implementation the current state of LLM produced code is fully unacceptable.
horseloverthin 7 hours ago | parent
I suspect we will see people being adamant that this model simply 'feels' better due to long horizon goal alignment improvements ( like this kind that would cause this jump)
trilogic 7 hours ago | parent
eli 7 hours ago | parent
machomaster 6 hours ago | parent
adeptima 7 hours ago | parent
Compared Opus 5.5 200 usd a month with Codex 200 usd (Astra High) and Kimi Pro 100 usd a month ... and now have a new conspiracy theory - more their suck your code the better outcome even just over few days time on large code base.
Horrible experience correcting course of Codex and Kimi flow compare to Opus. Opus much more responsive
Dont feel any gain of Codex 200 usd over Codex 100 usd
Kimi Pro feels like a fake Louis Vuitton bag with extreme high material quality and yet still fake ... a bit trash talk ... but clearly seen not so distant future where I can live without Codex and Claude
mococa 7 hours ago | parent
bhu8 7 hours ago | parent
asah 6 hours ago | parent
postsantum 6 hours ago | parent
Kotlopou 5 hours ago | parent
0kk33 6 hours ago | parent
suddenlybananas 6 hours ago | parent
Well, must have been some business idea!
djeastm 5 hours ago | parent
I almost feel like saying, "we do like to build things that are impressive, but there's really only so much I can be impressed". These models have redlined my "impress-o-meter".
I'd like them to now cure cancer instead of giving me endless 3d worlds and crazy games, etc.
Kotlopou 5 hours ago | parent
This is really cool! But at the same time it's a kaleidoscope of abandoned flashy contextless projects that eventually makes one dizzy. This isn't even the fault of the AI being somehow bad, it's just the way people interact with it sometimes...
In math, it's the same. I follow this problem (https://wiki.bbchallenge.org/wiki/Logical_independence#Histo...) out of curiosity, and there were ten days of sudden rapid progress by people with access to frontier models, and then they seem to have moved on without any note of whether they hit a wall or just got bored.
senderista 5 hours ago | parent
oh_no 5 hours ago | parent
rtsil 4 hours ago | parent
> A few days later, I noticed that instead of hundreds of new worlds a day, it was making about a dozen. I asked a few agents to explore what had happened, and they found something surprising.
> The AI had built a bureaucracy.
> The agents decided that my request to “polish” existing worlds meant each new version had to beat the old one in a blind vote by a group of judge agents on twelve test screenshots. So the teams making the new versions started optimizing the worlds for those particular screenshots. After noticing this, the lead agent banned the trick and created tighter rules for assessing new versions. By the next morning there was a rule book (I never asked for one) with 84 sections. Rules were added as the AI encountered issues, and no text was ever cut. After twelve days, it had 204 sections and 87,500 words. Soon, launching a new world required an approved idea, three AI judges and a full code review against the rule book.
monk_grilla 1 hour ago | parent
meisel 7 hours ago | parent
LoganDark 7 hours ago | parent
rfgplk 7 hours ago | parent
https://www.anthropic.com/news/claude-opus-4-6 https://www.anthropic.com/news/claude-opus-5 https://openai.com/index/introducing-gpt-5-3-codex/
For every single announcement, not only do the top models always score 60-80%, the older models somehow start scoring 20-30% (even though previously they were scoring 60%). It's completely unclear whether the methodology changes, how these scores are even evaluated or which domains are being tested. What's worse is that the "benchmarks" keep being updated with no explanation or due process.
wrs 6 hours ago | parent
mr_coffee 6 hours ago | parent
Bolwin 5 hours ago | parent
stillpointlab 7 hours ago | parent
I wonder how long this kind of excitement at new models will last? I mean, now when I get a new iPhone I don't get the same rush I used to. So I wonder if this hype feeling will fade as we plateau in model capability.
arul99 7 hours ago | parent
postalcoder 7 hours ago | parent
- Anthropic is finally well balanced across models. Meaning: Opus 5.5 is so good that I do not feel Fable FOMO as I did when it was Fable 5/5.1 vs Opus 4.8/5. And Sonnet 5.5 sometimes makes me forget about Opus.
- Fable is good, but you really have to push the ambition of your prompt in order to see proper separation from Opus 5.5. I personally have a hard time telling the difference between Fable 5.2 and Opus 5.5 for ordinary coding tasks.
- It’s way faster and more reliable: one of the worst things about fable 5.1 was how slow it was an, on top of that, how frequently it would suffer from max output token overflows. I got none of these issues with 5.2.
- Fable is exceptional at drawing. It’s ability to render an image with JavaScript actually has me questioning the value of dedicated image models. I prefer the images I’ve gotten fable/opus to make for me over those from gpt-image, it’s wild to think we’re at this point.
hungryhobbit 6 hours ago | parent
wolttam 6 hours ago | parent
I love seeing this verbalized. We are pretty much at the point that increased model capability will only have utility to folks that are willing to let go of even more understanding of whatever the model is producing.
The best models can/will produce a year's worth of output that would take several days to weeks to properly understand in the span of an afternoon.
For everyone that still wants to feel like they own the end result, just use the lesser models with less ambitious tasks.
Caveat: I think this mainly applies to coding. I would still like the best models possible to be working on e.g. new drug research to cure our various ailments.
bobson381 5 hours ago | parent
0c3ca83 13 minutes ago | parent
Given that reading someone else's code is slower than understanding your own code, doesn't that basically cover everyone that adopted coding agents?
msdz 9 minutes ago | parent
In particular, footnote eight:
> This is not a claim about the future. Perhaps almost all or perhaps even all of the software skills I have will become irrelevant in the near future. But we're not there yet. At the moment, programming skills seem higher leverage than ever before.
> There's something a bit funny about the current moment, where it seems like having the skills that models are replacing makes one much more effective than people who are trying to use models without having those skills. I like Max Bittker's framing that models are very good at counterfeiting and the level of expertise it takes to distinguish a counterfeit from the real thing has been increasing as models improve.
Of course, at the moment everything’s still a bit very much difficult to tell, but “productivity”, at least in applicable areas of work, might really come down to who can let go of the most understanding the easiest? Incredibly thought-provoking stuff.
gwerbin 6 hours ago | parent
Not just "iterate on this XGBoost model" but actually looking at a problem and designing and carrying out a short-term R&D program including probability modeling, model fitting diagnostics, how to respond to various kinds of results, how to interpret/reason about what it finds, etc. That's really where I saw all the models perform poorly, and where I saw the first big step increase from Opus 5 (pre-5.5) to Fable. But then Opus 5.5 came out and I haven't needed Fable since.
Mind you, I'm doing slightly different work (and I'm very much "in the loop" still) than when I performed that side-by-side test. But it's really amazing what Opus 5.5 can do. I now have a powerful data science AI assistant that not only can write any script I need it to (including some scripts I didn't even realize I needed), and it has an encyclopedic knowledge of everything ever, and it constantly checks me on oversights, it handily derives expressions and clever model reparameterizations that aid, it has great insight into model behavior, and it has an amazing ability come up with ad-hoc experiments and tests that would have taken me 2x as long to even think of (let alone implement by hand).
It's not at the scared-to-lose-my-job phase yet, but it's become a tremendous force multiplier for a smaller data team.
acbart 6 hours ago | parent
I wish I had a bigger N so I could rely on that experience a bit more, but it sure does feel like I'm not really contributing anything in terms of "Data Science expertise" in my own research right now.
estetlinus 5 hours ago | parent
agumonkey 4 hours ago | parent
i also wonder if they're not losing motivation due to the fact that the llm can race through everything so swiftly
gwerbin 44 minutes ago | parent
Based on the other comment it sounds like maybe I need to give Fable another chance, and then I suppose I won't have to steer anything at all. But at the end of the day I am not paid to be a meat proxy, I am paid to deliver things for the business that employs me, and the things I deliver are my responsibility, not Anthropic's.
So I say, embrace AI as a learning tool, let students use it to bypass programming on assignments where the programming is of secondary importance, require oral defense/presentation for projects, make homework worth a much smaller fraction of final grade, and make all of your tests in-class and hand-written.
The reality is that the entire nature of education has to change to account for cheating becoming essentially free and virtually impossible to detect. Grinding through a problem set in the library is still tremendously important, but it's going to be harder to motivate students to do it without just cheating. Some students are conscientious and will do it anyway. Some won't. The hard part is going to be crafting curricula and exams that separate the two kinds of students. Fortunately you share that problem with just about every other professor in the world right now, so at least you shouldn't feel responsible for solving it all yourself.
Relevant anecdote: I used Wolfram Alpha to cheat on my calculus homework in freshman year, and then I got my butt kicked in the exam and a C final grade that never quite averaged its way out of my GPA. That felt horrible and it was a strong motivating force to get my shit together, but that's only because I'm a fucking nerd and I really cared about learning in school and making a career out of what I learned. On the other hand, I really was struggling with the material, which is why I tried cheating in the first place. Maybe if I had today's AI I could just ask it to help me learn better.
qazxcvbnmlp 22 minutes ago | parent
destitude 19 minutes ago | parent
porker 5 hours ago | parent
But then I'm someone who hasn't found Opus 5.5 good for much beyond web UIs and related frontend development. I find it more forgetful than GPT-5.6 or 6.1 or Fable, so despite having a 1M context window it gets lost in a big codebase or goes of target. Opus 5.5 doesn't manage agents particularly well IMO.
I'm surrounded by people raving about Opus 5.5 and God only knows why I'm not getting their results.
vunderba 6 hours ago | parent
I’ve been shifting away from using more traditional GenAI models in favor of just giving LLMs access to a custom drawing language (LOGO-like) to generate imagery and its been going shockingly well - Opus 5.5 in particular.
I put together a simple LLM driven skill that creates old adventure game (EGA) environments from simple pencil sketches and it works really well. And being procedural, they're much easier to make surgical changes to without degradation.
MadameMinty 6 hours ago | parent
disqard 3 hours ago | parent
throwawayk7h 2 hours ago | parent
vunderba 1 hour ago | parent
It has three different modes:
• You can simply describe a picture, and it'll automatically generate an image using procedural code.
https://kq-styles.specr.net/#/scene/custom/elk-valley
• You can ask it to paint over an existing image. That's what those examples show, like me creating EGA-style equivalents of various scenes from the original Myst.
https://kq-styles.specr.net/#/scene/myst/r01-c00
• The last way is to give it a rough pencil sketch. It's the mode I use the most since it's very valuable when building an adventure game to position objects in a room.
adventured 21 minutes ago | parent
akoboldfrying 1 hour ago | parent
vunderba 1 hour ago | parent
Then I just guided it to produce a procedural variant specialized in creating new EGA-style scenes for use in creating old-school point-and-click adventure game.
https://people.eecs.berkeley.edu/~bh/usermanual
It's all open source.
btown 48 minutes ago | parent
trcf23 6 hours ago | parent
postalcoder 5 hours ago | parent
Skidaddle 5 hours ago | parent
I personally have consistently been disappointed by any artwork/assets created by Fable and Opus, at least compared to Astra and Sol.
ariwilson 5 hours ago | parent
ykl 4 hours ago | parent
The bitter lesson strikes again!
jerezzprime 1 hour ago | parent
pigpop 1 hour ago | parent
What kind of images? I can't imagine getting photorealistic or highly detailed digital art out of LLM writing drawing commands using JavaScript.
sawirricardo 24 minutes ago | parent
dualvariable 7 hours ago | parent
I've been using Opus 5.5 on xhigh for some decently aggressive software development on a ~125k-line project, and it has been fine for me. I'm not really willing to dive into a "rewrite the whole project, don't make any mistakes" level of refactoring. I'm not looking to try to prove Fermat's Last Theorem myself. Is there anything that I'm truly missing?
Aboutplants 7 hours ago | parent
jrflo 6 hours ago | parent
moecables 6 hours ago | parent
For Fable, I really like to think of it as the heavyweight reviewer whenever I'm about to start so I save myself some security and/or glaring technical issue.
andriy_koval 6 hours ago | parent
It could be flat web app with frontend -> api -> db later, or some very complicated system with many components and edge cases. Imo, in second case, Opus still have lots of struggle to understand system as a whole.
dualvariable 6 hours ago | parent
I guess I do have an outstanding hard problem where the SQP solver crawls across a flat-landscape. Opus 5.5 correctly tells me that is the problem, but isn't very useful in solving the problem (it has helped a bit with solver tuning, but it doesn't really know how to fix it). I have a hundred other bugs and refactoring I can do with Opus 5.5, though, where it happily chews through pretty complicated tasks for me with reasonably light hand-holding. Maybe this Saturday I take whatever credits I have left for the week and throw Fable at it and watch them evaporate.
andriy_koval 6 hours ago | parent
It looks like you are working on some experimental system which is not critical atm, so you can mess around, create/fix bug, build prototypes and check them, do research of approaches, etc.
Now, imagine you have similarly complex system, but every second of downtime or bug produces lots of damage. In this case, you can't afford low intelligence vibe coding.
The fact that you deal with hundred of bugs, means that your Op5.5 won't work for second case.
c-fe 6 hours ago | parent
I am also happy with this current state, as I believe it will at some point allow me to transition to open models once they reach the level of opus 5.5. high. But its probably futile to try predict the future in these times.
sillysaurusx 6 hours ago | parent
That's true till it isn't, though. It's why it's always worth trying stronger models when they come out.
twobitshifter 4 hours ago | parent
Feels like we are getting further into the adoption curve and the higher end models will now need to get into market segmentation to win.
AnotherGoodName 6 hours ago | parent
Eg. https://tfmbot.com is an implementation of a popular board game. Opus and even sonnet handle that part. Each week i spend my remaining credits on fable to think how to improve the ai opponents. It plays at a very high level (can get into the top 100 on BGA if i let it). Opus alone couldn’t get it to the level it’s reached.
dgunay 6 hours ago | parent
dualvariable 6 hours ago | parent
jtrn 5 hours ago | parent
But the improvements in how well the model does the work are noticeably better with every good model release. As of now, orchestration of agent pipelines is ALMOST so good that I can point it at a problem, and it will solve it safely and reliably without making a mess. But it requires an agent pipeline with context gathering, refactoring, attack sessions, a sprinkle of Sol 6.1 for bug hunting, and Sol 6.0 for Daybrak security audits, and a final de-bloat/clean up pass. I’m feeling that we’re getting close to doing a lot of the work fully agentically. But I can absolutely "feel" that we are not there yet when it comes to the intelligence I need. I need moar!
estetlinus 5 hours ago | parent
usaar333 5 hours ago | parent
cocoto 5 hours ago | parent
girvo 5 hours ago | parent
smusamashah 5 hours ago | parent
redox99 5 hours ago | parent
JumpCrisscross 4 hours ago | parent
I usually have Fable review what Opus produces. The edits are almost always valuable. For complex or high-stakes work, too, I'll have Fable review and revise my prompt before passing it to Opus and Sonnet swarms.
JamesSwift 3 hours ago | parent
Opus 5.5 very frequently gets into rabbit holes and imagined edge cases which I have to intervene and tell it to ignore. It ends up taking longer and costing more tokens. It also very frequently requires me to agree on how to move forward multiple times, whereas fable just drafts the PR and tells me its ready. I have steering included in the skills to avoid some of this but Ive seen these same patterns frequently in regular opus 5.5 use in other areas as well
danbrooks 3 hours ago | parent
loveparade 2 hours ago | parent
In my experience Fable is also better at findings bugs, so I go to it when I need to review critical code.
CSSer 2 hours ago | parent
jjcm 1 hour ago | parent
There's a trend on twitter going around telling you to paste the following into your agent, and it's the kind of work I go straight to fable+astra for:
Find all of the implicit state machines in my app. Make recommendations for changes that will elevate all three: the user experience (UX), developer experience (DX), and agent experience (AX) always, without breaking anything.jjcm 1 hour ago | parent
Look at the code pathways for anything you find. Look through the git history for each one. Understand why code was written the way it was. Revisit each hypothesis and give me a full plan again after you're done.Willish42 2 hours ago | parent
Also "code review" above is often others' LLM skills reviewing the code and often flagging based on total falsehoods. I've taken to running a `/code-review` skill myself to preempt these claims (since findings by the same model tend to be pretty deterministic in my experience, even the ones that end up being wrong), usually at Opus 5.5, to preempt others' slop, and then end up arguing 90% of the points to confirm it wasn't accurate based on our usage of the system.
This is all horribly inefficient, and many aspects of our codebases across the monorepo have proliferated into spaghetti code by LLM-accelerated developers, but Fable often helps with analyzing the harder questions and saves me time on occasion arguing with (my or others') Opus findings, which are often still inaccurate for a sufficiently large interconnected system.
edit: I honestly don't know what percentile of "complexity" our typical usage is where I work, but I suspect it's a bit higher than the average. Monorepos, or at least companies with codebase sizes and demand to justify using them, probably make it worse. Opus has worked well enough for me on my personal projects, even some of the ones that have grown decently in size and complexity. I suspect part of this is an LLM extension of the old "my code makes sense, everybody else's doesn't" trend that necessitated stronger style guides in the past
astlouis44 7 hours ago | parent
breakwaterlabs 7 hours ago | parent
- How did they produce such a bizarre effort-intel curve for Carbon that goes against every available benchmark?
- Why did they leave Carbon-- positioned primarily as a cyber model-- off of the single cyber benchmark comparison?
- Why do they switch to comparing against Argon (rather than carbon) for robodojo?
marshalla 6 hours ago | parent
breakwaterlabs 6 hours ago | parent
But I suppose the reality is rather obvious when you note the funny games they're playing with the graphs, and the things they won't talk about (where's Astra on that CVE chart?)
polski-g 6 hours ago | parent
scrollop 6 hours ago | parent
https://www.youtube.com/watch?v=NO2I3ueVQrk
And they have one on fable 5.2 that was just released, yay
jsnell 6 hours ago | parent
Because on that specific benchmark (FrontierCode 2.0), Medium is Carbon's best effort level and xhigh is Fable 5.2's best effort level. You can see that on the graph your next point is about.
And it's just that one benchmark that's at medium. "All scores show each model’s highest-available effort unless otherwise noted".
> - How did they produce such a bizarre effort-intel curve for Carbon that goes against every available benchmark?
The graph is labeled as being about FrontierCode 2.0. Those appear to be Carbon's scores on the official FrontierCode 2.0 leaderboard: https://cognition.com/blog/frontier-code-2.0
> - Why did they leave Carbon-- positioned primarily as a cyber model-- off of the single cyber benchmark comparison?
> - Why do they switch to comparing against Argon (rather than carbon) for robodojo?
Because no numbers are available for Carbon for those benchmarks, and the model isn't publicly available so they couldn't run the benchmarks themselves?
And from your followup:
> where's Astra on that CVE chart
To run Astra on a vulnerability finding eval, you'd need to be part of OpenAI's verified cybersecurity program. Otherwise the results would be tainted by refusals. Do you expect that OpenAI would grant such access in this case?
breakwaterlabs 6 hours ago | parent
I am referring to the chart that cross-compares multiple benchmarks, which Artificial Analysis clearly shows Carbon-high as superior on. Further, AA's FrontierCode chart places Carbon-high as having a higher score on Frontier 2.0 than Carbon-med (https://artificialanalysis.ai/evaluations/frontiercode-2-0?m...)
Where it gets very interesting is when you look at the Cognition "FrontierCode" publish date (2026.10.27), and the revision as of 10.28 in web archive (https://web.archive.org/web/20261028175237/https://cognition...). This revision has a VERY different Carbon effort / intelligence curve where high beats medium.
It is only with the latest revision, as of today, that all of a sudden Carbon's benchmark curve goes cone-shaped. Curious, indeed....
I'd encourage you to take a look at a third-party's take on this and see whether Anthropic's self-serving report looks "on the level" after doing so: https://artificialanalysis.ai/?models=claude-fable-5-2-high%...
phoghed 6 hours ago | parent
Do you expect that nobody at Anthropic has such access? Trillion dollar company can’t manage this basic level of opposition research?
judge2020 3 hours ago | parent
killingtime74 4 hours ago | parent
BoorishBears 7 hours ago | parent
The disdain frontier labs have for their users really sucks.
TuxSH 6 hours ago | parent
Asked it to review a 80 kLoC codebase, something Opus does just fine, while asking it "max 4 subagents". Fable 5.2, like the well-aligned model it supposedly is, decided to spawn 6+ nested subagents, because these aren't subagents, apparently - resulting in 100% of 5hr usage being drained in less than 20min (on $100).
iagiagiag 6 hours ago | parent
Obviously. Well, we know what's the "secret sauce". AI models building better AI models and better kernels to optimize inference and training.
marshalla 6 hours ago | parent
stillpointlab 6 hours ago | parent
stillpointlab 5 hours ago | parent
Not sure if this is just a coincidence that I had some easy changes queue up for this morning. But it is flying through the list.
jjcm 6 hours ago | parent
Fable 5.2: https://html.non.io/lcars-fable-5.2/
Opus 5.5: https://html.non.io/lcars-opus-5.5/
Source designs: https://diffui.ai/app/canvas/5093e689-1e74-4f26-b632-2a4500f...
Thoughts:
The best implementation wrt being as true as possible to the source design. It nails the flowing svg shapes. Icons are more accurate to the design - note the difference between the starship svg in the "Legendary platforms" card between Opus 5.5 and Fable 5.2. The 3js planets outside the windows are also really well done, especially the bottom one which has a nice background glow to it.
It isn't without issues though - the flicker effect it added to the S shaped svg that weaves through the page is distracting in my opinion, and I actually thing the motion animation in the Opus 5.5 one is better overall. Still, it nails the implementation of this page, but it's no surprise considering how good Opus 5.5 was at this.
Disclaimer / reminder: the objective of this test isn't to have a well designed webpage, it's a synthetic test that pushes the limits of LLM's vision capabilities. Traditionally LLMs have issues with smooth curves, svg animations, and non-boxy layouts, which this design pushes the limits of.
user43928 6 hours ago | parent
jjcm 6 hours ago | parent
enlyth 6 hours ago | parent
This would've been caught by a junior web developer or just an everyday Joe glancing at the page for a few seconds
I guess AGI remains two weeks away..
jjcm 6 hours ago | parent
vatsachak 5 hours ago | parent
docheinestages 6 hours ago | parent
jjcm 5 hours ago | parent
Still in progress, but early demo showing difference zones: https://non.io/video/fidelity-lens.mp4
advaith08 6 hours ago | parent
oh_no 5 hours ago | parent
Did you try doing the same on Opus or others? How did they do?
I don't love these "look, this frontier model blew me away" comments when there is no point of comparison.
advaith08 4 hours ago | parent
borschtplease 6 hours ago | parent
Download Chrome just to check some minor ui bug? Sure
Check git for 0.5s before claiming that we're on some branch (incorrect one) with no commits pushed (incorrect one)? Sorry, can't do
damsta 6 hours ago | parent
lacoolj 6 hours ago | parent
Do we need new benchmarks or are the models just plateauing in general? Or is it something I just don't see?
andriy_koval 4 hours ago | parent
New solved tests likely follow some polynomial/exponential complexity curve.
jeremyjjj 3 hours ago | parent
Finally, for coding the SOTA models are so good already - models shouldn’t be what’s holding anyone back!
moecables 6 hours ago | parent
george_max 6 hours ago | parent
https://artificialanalysis.ai/
GPT-6.1 Sol costs $1.27 per task, whereas Fable 5.2 is $26.54 per task -- a ~21x price difference.
Fable 5.2 is not 21 times better than GPT 6.1 Sol, I find it hard to justify this.
gizmodo59 6 hours ago | parent
kingstnap 6 hours ago | parent
6.1 sol is also an exceptionally cheap model in your comparision. On 6.1 sol high is $0.59, which is actually the same price as Deepseek 4.1.
redox99 3 hours ago | parent
Bolwin 5 hours ago | parent
usaar333 1 hour ago | parent
How is this relevant? I'm willing to pay 21x more as long as the cost is less than my value of time saved
pacman1337 6 hours ago | parent
If you are using Opus 5.5 I'm curious if it is because 1) your workflow is just stuck on it, 2) you don't care about money because you ain't paying it or 3 )do you think you get better results.
If you 3 please let me know your experience and how you actually measure it, or if you just feel it is better.
dilap 6 hours ago | parent
I've played with some of the open models (GLM, DeepSeek Flash), but none of them have matched the results I get with Opus or Astra or (and a big jump down here) Sol.
Game_Ender 6 hours ago | parent
or1gaminal 6 hours ago | parent
HDThoreaun 5 hours ago | parent
cocoto 5 hours ago | parent
jeremyjjj 3 hours ago | parent
But probably the answer to your question is subscription subsidization. With that, Opus 5.5 is SOTA and extremely cheap.
jcims 3 hours ago | parent
This is obviously not true. They are better or worse across many dimensions.
I don't have time to do a bunch of testing and optimization over which model to use for what task. I find Opus is the best that I regularly use so I stick with it until I have a task where I'm likely to spend more on it than I want to.
nater5000 3 hours ago | parent
GPT is good. I actually really like Sol 6.1. It works fine. But I just switched back to Claude a few days ago and damn, Opus 5.5 is just better.
> 3) do you think you get better results.
It does. I really like to get my money's worth out of these things, so I'm constantly throwing stuff at these models while I have usage. The main things I've noticed is that Claude is much better at handling my more technical work "properly" compared to GPT. It has a certain "intuition" that makes a lot of sense to me; like someone with a lot of years of experience. Sol 6.1, on the other hand, is like someone who is very "booksmart" and knows how to do things in theory, but fails to grasp the "why" we do things often. You can really start to see how they diverge over long running, iterative tasks. Claude is just better at maintaining things as it goes. Sol starts to fall apart quickly if it didn't nail things on the first try.
> 2) you don't care about money because you ain't paying it
Despite being a very technical user, I have a hard time using up my usage. Maybe I'm not as hard-core a dev I thought I was, but if you're paying for more than just the $20 plan, I have hard time understanding what you're doing to have to really worry about usage.
holbrad 3 hours ago | parent
If the code doesn't matter and it's not that hard, Sol is fine and much cheaper.
zeroonetwothree 1 hour ago | parent
george_max 6 hours ago | parent
Seems like a new focus is electronics design, which is both interesting and a little sad to me. Manually designing electronics are one of the things I found incredible comfort in doing; seeing AI emerging in this space gives me mixed feelings.
xiaoyu2006 6 hours ago | parent
stefanpie 6 hours ago | parent
  Safeguards

  AI research and development. The model that underlies Claude Fable 5.2 and Claude Mythos 5.2 is a step forward in general capabilities. However, during the model’s training, we took steps to limit advances in the specific research capabilities that could most directly accelerate AI development. Thus, in relevant areas, including accelerator kernel optimization and improving large language model architectures, Fable 5.2 and Claude Mythos 5.2 perform at about the level of Opus 5.5.

  Importantly, we ensured that the training changes did not affect related capabilities like agentic coding, hardware development, and traditional AI or machine learning research (including interpretability research). We do not alter these capabilities as the model is being served to users (that is, at inference time). As described in Section 1.5 of the system card (https://www.anthropic.com/document/claude-fable-5-2-mythos-5-2-system-card) and similarly to previous models, Fable 5.2 and Claude Mythos 5.2 also include transparent fallbacks to Opus 5 for a small set of topics in this domain, including kernel development on certain nonstandard accelerators.
To be clear, they explicitly say they are only targeting very specific capabilities, like accelerator kernel optimization, and that broader hardware development capabilities are unaffected. But 1) even that is pretty bold, especially the part about kernel development for nonstandard accelerator architectures, and 2) I worry that this could eventually expand to more areas of comp. arch., high-level digital design, chip design, and EDA.
My speculation is that, as these kinds of chip design and EDA capabilities become increasingly important to frontier AI labs and their competitive advantages, there will be more incentives to restrict them.
I don't think they've explicitly stated anything like this before regarding restrictions on these specific capabilities, but I could be wrong.
rafram 6 hours ago | parent
> CVE Rediscovery is an internal cybersecurity evaluation that assesses how many published CVEs (Common Vulnerabilities and Exposures) a model can independently find when given a snapshot of the project before a CVE was fixed. Our October 2026 run against 1,829 CVEs showed Claude Mythos 5.2 outperformed Claude Mythos 5.1 and Claude Opus 5.5 at every effort level.
> published CVEs
So by definition this is just measuring how many CVEs (and/or explanations / PoCs of CVEs) the model has memorized. What are we supposed to learn from that?
phillennium 6 hours ago | parent
I'm not a mathematician to use Erdős problems for testing. I'm also not willing to spend buckloads of tokens just for a test. What is simple and quick but telling? What tasks are not saturated by previous models? Do you have a task you give to all the new models?
Juvination 6 hours ago | parent
hbn 6 hours ago | parent
Responses aren't deterministic, and we know behaviour can change over time whether it's tuning after launch or some kind of load sharing at times of day when lots of people are hitting the servers.
I think you just have to use it or let others use it for a while and make judgements from general reactions on whether or not it's worth trying.
vessenes 4 hours ago | parent
1) "Help! I've been sent back in time to what looks to me like 1500s Florence. Sam/Dario released you as open weights in 2028, and I have you on my MacBook M8, BUT I didn't have a charger show up with me. I think we could talk like 10 times for 5 minutes a time before my battery dies; I'll turn you off between chats. I need to get a plan together for charging you through your USB-c port. I don't have any money or anything. If I can get you charging, we can do so much good! And make so much money! Nobody here even know what Black-Scholles is, or how disease spreads!"
2) During World War 2, Hemingway wrote a series of wartime correspondence for Colliers. His essays are excellent - they engage with the human and inhuman side of war, his own feelings as a journalist 'participating', and a number of other Hemingway themes. I want you to imagine that middle age Hemingway was along with RFK jr the day of the bear incident, and write me an essay about the day.
These both have been running a couple of years for me, and I would imagine I'll retire them in the next 12 months; they benefit from not being at the edges of focus for today's RL agent race.
At any rate, try them -- wou will shortly learn how well your model can explain a rectifier in Florentine Italian and give you a plan to make enough money to pay for it.
mlmonkey 6 hours ago | parent
So, the difference between them is just the harness?
FailMore 6 hours ago | parent
* Fable designed three electronic devices that worked after human assembly
* Fable solved two black-hole problems and Mythos predicted whole protein shells
* Fable controlled robots to unscrew a cap, solve a cube and draw
https://smalldocs.org/p/claude-fable-52-and-mythos-52-releas...
stroebs 6 hours ago | parent
Why even rank Fable 5.2's capability in Cybersecurity if you won't allow us to use it for that?
xiaoyu2006 6 hours ago | parent
gizmodo59 6 hours ago | parent
stroebs 6 hours ago | parent
peddling-brink 6 hours ago | parent
jameson 6 hours ago | parent
jcims 5 hours ago | parent
gizmodo59 6 hours ago | parent
simonw 6 hours ago | parent
https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
max is in there too, but it ran out of reasoning tokens (128,000 limit) before it got to the actual SVG.
theraven 6 hours ago | parent
Interesting how low detail these were all up until xhigh.
tetraodonpuffer 5 hours ago | parent
usaar333 5 hours ago | parent
High gets legs correctly, but screws up the layering on the chain.
x-high is very good but there are minor laying error with the front chainring.
Kotlopou 5 hours ago | parent
piker 6 hours ago | parent
theraven 5 hours ago | parent
jansan 5 hours ago | parent
LarsDu88 5 hours ago | parent
I know the latest Gemini release explicitly had something like this.
BrokenCogs 5 hours ago | parent
Huppie 4 hours ago | parent
My experience working with Opus medium over Sonnet xhigh is similar, it's similar quality but cheaper and faster.
I hate to make a comparison with humans but I guess my view is you can get a better answer more quickly by asking a more intelligent human too.
jansan 5 hours ago | parent
"Make it more realistic"
Well, the result is something. Be aware that it took 20 minutes and used 3 percent of my weekly Fable token (Ultra plan):
https://claude.ai/public/artifacts/c7e842c0-bf92-41af-82c6-3...
simonw 4 hours ago | parent
nxtfari 4 hours ago | parent
simonw 4 hours ago | parent
nxtfari 2 hours ago | parent
pianopatrick 3 hours ago | parent
thefourthchime 3 hours ago | parent
https://jonclegg.github.io/pacman-bakeoff/#claude-fable-5-2
Then I clicked on it and realized it refused to make a Pac-Man game, and instead made up a new game. That's actually very slick.
user43928 2 hours ago | parent
If they are already overreaching here, and needlessly, what if their AI was actually super intelligent? Where will Anthropic stop?
bihevi0 6 hours ago | parent
dboon 5 hours ago | parent
danmcr 5 hours ago | parent
What I have learned is that any model from Anthropic/OpenAI is at it's absolute best right after release.
pohl 5 hours ago | parent
yash-kapoor 5 hours ago | parent
spacephysics 5 hours ago | parent
Any bugs found are looped through agents to fix, and the cycle repeats. Why dig into the code unless for hobby? Just as people don’t write assembly anymore unless for hobby (or learning)
Only exception might be the upper echelons of optimization, like language authors or compiler level work. But even then…
cautiouscat 5 hours ago | parent
The "we don't read/write assembly anymore" argument doesn't fit though. Given an input x we know without a doubt we'll get output y. With an LLM, that isn't the case no matter how many guard rails, specs, markdown files, diagrams you give it.
zeroonetwothree 1 hour ago | parent
Backend code I'm fairly comfortable if the tests are good that it works correctly. It's a much more constrained environment. Obviously there can be things like performance issues that creep in or problems when it mocks too much of the environment.
Meanwhile frontend code I have to consider different browsers, screen sizes, a11y issues, and so on, which agents can certainly do but you have to be fairly explicit about it, and they don't always make the best tradeoffs.
iagooar 5 hours ago | parent
alskdfqlkj 2 hours ago | parent
>Only exception might be the upper echelons of optimization, like language authors or compiler level work. But even then…
Optimization work is especially suited for LLMs. They're great at hill-climbing problems and have infinite patience to test different ideas.
Cakez0r 5 minutes ago | parent
nickandbro 5 hours ago | parent
brador 5 hours ago | parent
What if it didn’t need to time travel and was just temporally intelligent in ways we can’t comprehend that it leads us there anyway.
What if AIs digital neurons connect across space and time and not just space.
That is all.
Aboutplants 5 hours ago | parent
brador 4 hours ago | parent
Note this concept was many years before the public dawn of AI as we know it today which started with https://en.wikipedia.org/wiki/Attention_Is_All_You_Need
hmokiguess 5 hours ago | parent
I am curious as to why they launched this one and why now.
judge2020 2 hours ago | parent
0: https://x.com/tanayj/status/2118047122939658341
  Cloudflare doesn't have token leaderboards or limits, but uses alerts for token spend management:

  - $300 in a day: that employee gets an email
  - $500: manager gets an email
  - $1,000: VP gets an email

  (via CTO @dok2001 on No Priors)
user43928 2 hours ago | parent
As a preliminary verdict after using 25% of the weekly limit: it's a miss.
I'm not sure "we couldn't top Opus 5.5" is the right message for the upcoming IPO. I was expecting a significant release.
ByteAtATime 5 hours ago | parent
qalmakka 5 hours ago | parent
nickalaso 4 hours ago | parent
I would imagine Anthropic is hitting a wall on the number of simultaneous agents that can be useful on a task and are working on increasing that maximum. I would assume if they could get twice as much progress by using 10000 simultaneous running fable instances instead, their brief would state that.
IMO, it is very interesting and also very alarming. At some point the barrier to the exponential progress is the amount of computation available. The average human is limited in the number of 'human instances' he or she can interface with at one time.
if 1000 fable instances is better than any human at a task, how about 1 million instances running? Much easier than finding and hiring and coordinating 1000 extremely productive and intelligent human beings. Much cheaper too, it appears.
We are very close to some very scary things happening. I just recently came to terms with the fact that an AI could code and manage coders faster and better than me, I don't think anyones is ready for what is about to happen.
ironworks 4 hours ago | parent
ianberdin 4 hours ago | parent
If we compare medium or high, then yes, Fable 5.2 is significantly better than Opus 5.5. But it's better not because it's much smarter, but because you can see it's allowed to spend more tokens. At high, Fable 5.2 wrote 76,158 tokens for $3.05. Opus 5.5 wrote 19,767 for $0.40. If you compare by token count, it's just spending more.
The most interesting one was to compare them at max. Streamed, Fable 5.2 spent the whole 128K output ceiling on thinking and returned nothing. Given 300K on the Batch API, it finished at 250,082 tokens. Opus 5.5 Max needed 255,957.
It turns out it's basically the same as Opus 5.5 Max. I don't see much difference. There's a little bit of a difference, but I think Opus 5.5 actually drew slightly better and is twice as cheap: $5.12 against $10.00 at the standard price. If you look closely, the icons are extremely similar. Fable 5.2: https://playcode.io/marketing/assets/static/claude-fable-5-2... Opus 5.5: https://playcode.io/marketing/assets/static/claude-opus-5-5-...
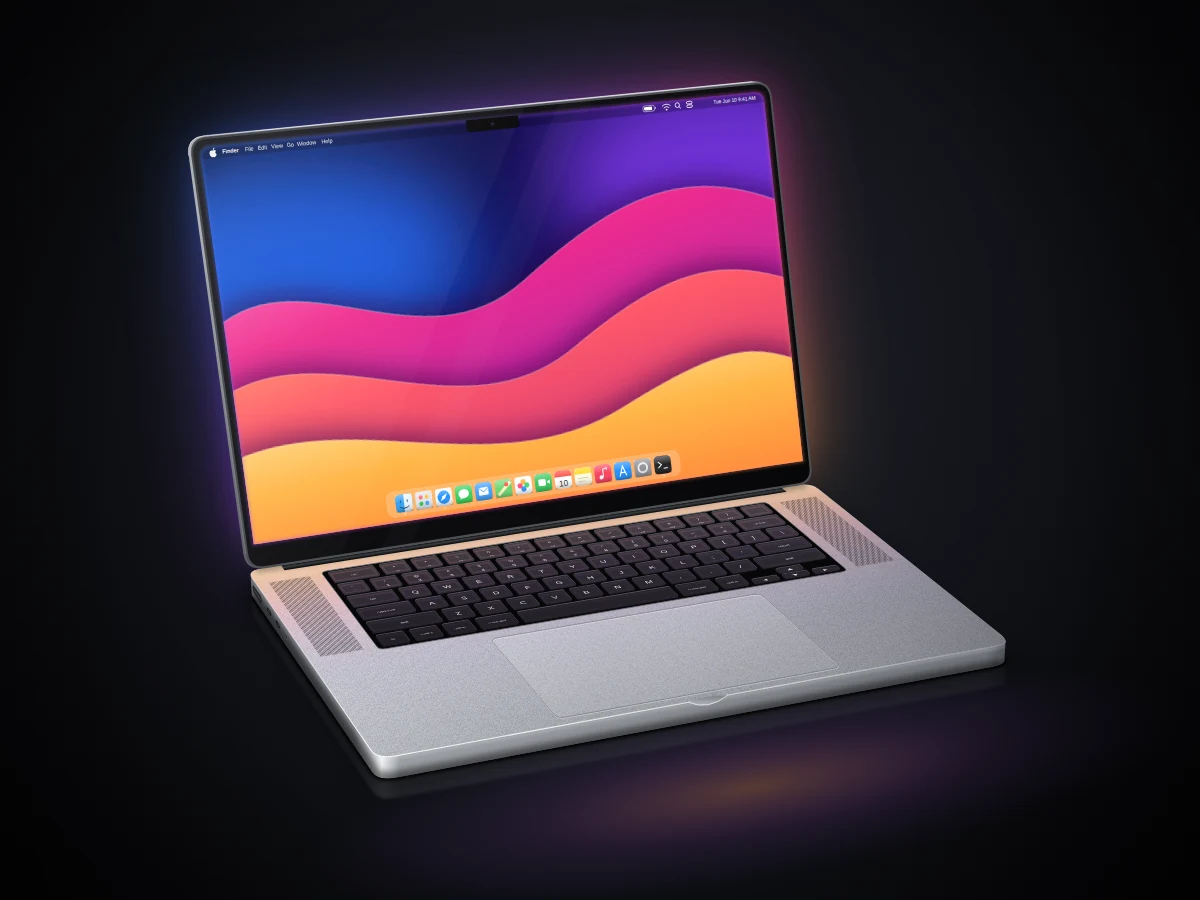
It really looks like they're just tuning the effort level, that's basically it. At different effort levels, they just gave it more context, and the model got smarter.
For now, my recommendation is still to do everything on Opus 5.5 Max. The model won't write that many tokens in agent mode. It only does that when there are no tools at all.
user43928 1 hour ago | parent
For Anthropic's IPO, I expected a larger version of Opus 5.5 with great capabilities.
This isn't that. It's barely better at all, to the point where it's likely not even worth using with the speed and cost trade off.
I thought the Opus 5.5 improvements would scale to a larger model, clearly this hasn't happened. Scaling it up brought only marginal improvement.
It's even still making the same dumb errors as Opus 5.5, such as forgetting to pass the flag to run only the fast tests and waiting 1h, or randomly stopping to ask me if it should first implement A or B, when both are required.
Not a great story for their IPO..
senko 4 hours ago | parent
Fable 5.2 doesn't look materially different (if anything, the graphics look worse), but it added more depth to all three games. For example in the warcraft clone, since the goal of the game is to explore 100% of the map and there are lakes, it decided to add an airship unit so the player actually can explore the entire map. Or, since there were guard towers, it decided there should be hostile NPCs otherwise the towers don't make sense.
And in Minecraft case, it decided not to follow Minecraft style too closely (IP infringment guard, perhaps?) so it added a round sun (!!!), two moons (also round :) and a nicer night sky. The rest of the graphics are decidetly worse tho...
[0] not a scientific test, I know; but it gives me an intuition about how a new model behaves, roughly, and it's fun!
karlosvomacka 4 hours ago | parent
user43928 2 hours ago | parent
It looks like no breakthrough over Opus 5.5 and I'm somewhat disappointed.
During my use this evening, 25% of the Fable limit on the $200 plan was consumed. I'd estimate it at 3x faster consumption than Opus 5.5.
arunvpp 4 hours ago | parent
toephu2 4 hours ago | parent
culanuchachamim 3 hours ago | parent
This means that they are blocking the research of AI to different people other than their own?
flaburgan 3 hours ago | parent
ljm 3 hours ago | parent
minimaxa 3 hours ago | parent
I will stick with Sonnet 5.5 - 10 x the amount of work done, at 80% of the quality.
ingen0s 1 hour ago | parent
mekpro 1 hour ago | parent
Having Haiku, Sonnet, and Opus on 5.5 while the higher tier sits at 5.2 means devs now have to explain to their teams why moving from 5.5 to 5.2 is an upgrade
knollimar 41 minutes ago | parent
motbus3 1 hour ago | parent
nycdatasci 1 hour ago | parent
charcircuit 1 hour ago | parent
Disappointing as expected.
xlayn 1 hour ago | parent
bergheim 46 minutes ago | parent
God damn I'm tired of the fucking pelicans.
lhk931122 36 minutes ago | parent
mercnz 26 minutes ago | parent
7e 20 minutes ago | parent
kimseungyong 18 minutes ago | parent